Document analysis vs data extraction: what each one is, with examples
For operations teams, analysts and students. What the two terms mean, how they differ, and how they work together in business and in research.
Key takeaways
- Document analysis interprets documents to answer a question. It classifies, summarizes, compares or evaluates them. Data extraction pulls exact values out of documents into structured data, such as an invoice number, a date or a balance.
- In business, extraction usually comes first, because analysis needs the values in a structured form before it can compare documents or check them against rules.
- In qualitative research, document analysis is a research method of its own. The READ approach breaks it into four steps. They are to ready your materials, extract data, analyze data and distill your findings.
- Extraction can run with little manual work, with a person checking only the values the software is unsure of. A person still makes the final judgment in analysis, but works from data that software has already extracted and checked.
On this page
Document analysis is the review of a set of documents to answer a question. It can mean sorting them into types, comparing them or checking them against rules. Data extraction is the narrower job of pulling exact values out of documents and into structured data. Examples are an invoice number, a due date or a closing balance. In business, extraction usually comes first, and analysis uses what it finds. In qualitative research, document analysis is also a method of its own.
What is document analysis?
Document analysis means reading documents with a question in mind and recording what you find in a consistent way. The term has three common uses.
In business
Reviewing documents to reach a decision, for example by comparing them with each other or checking them against rules. A lender's review of a loan file and a legal team's contract review are both document analysis.In qualitative research
A systematic procedure for reviewing or evaluating documents as evidence. Researchers use it to give context, generate questions, track change over time and corroborate other sources, such as interviews.In history classes
Examining a primary source, such as a letter, photograph or poster, and using it as historical evidence. The National Archives' worksheets take students through the same four steps for every kind of source.
What is data extraction?
Data extraction pulls specific values out of a source and puts them in a structured format, such as JSON, a spreadsheet or database fields. On business documents, the software first reads the page. For scans and photos, it uses OCR, which reads text from images. Then it works out where each part sits on the page and labels each value, such as the vendor and the total.
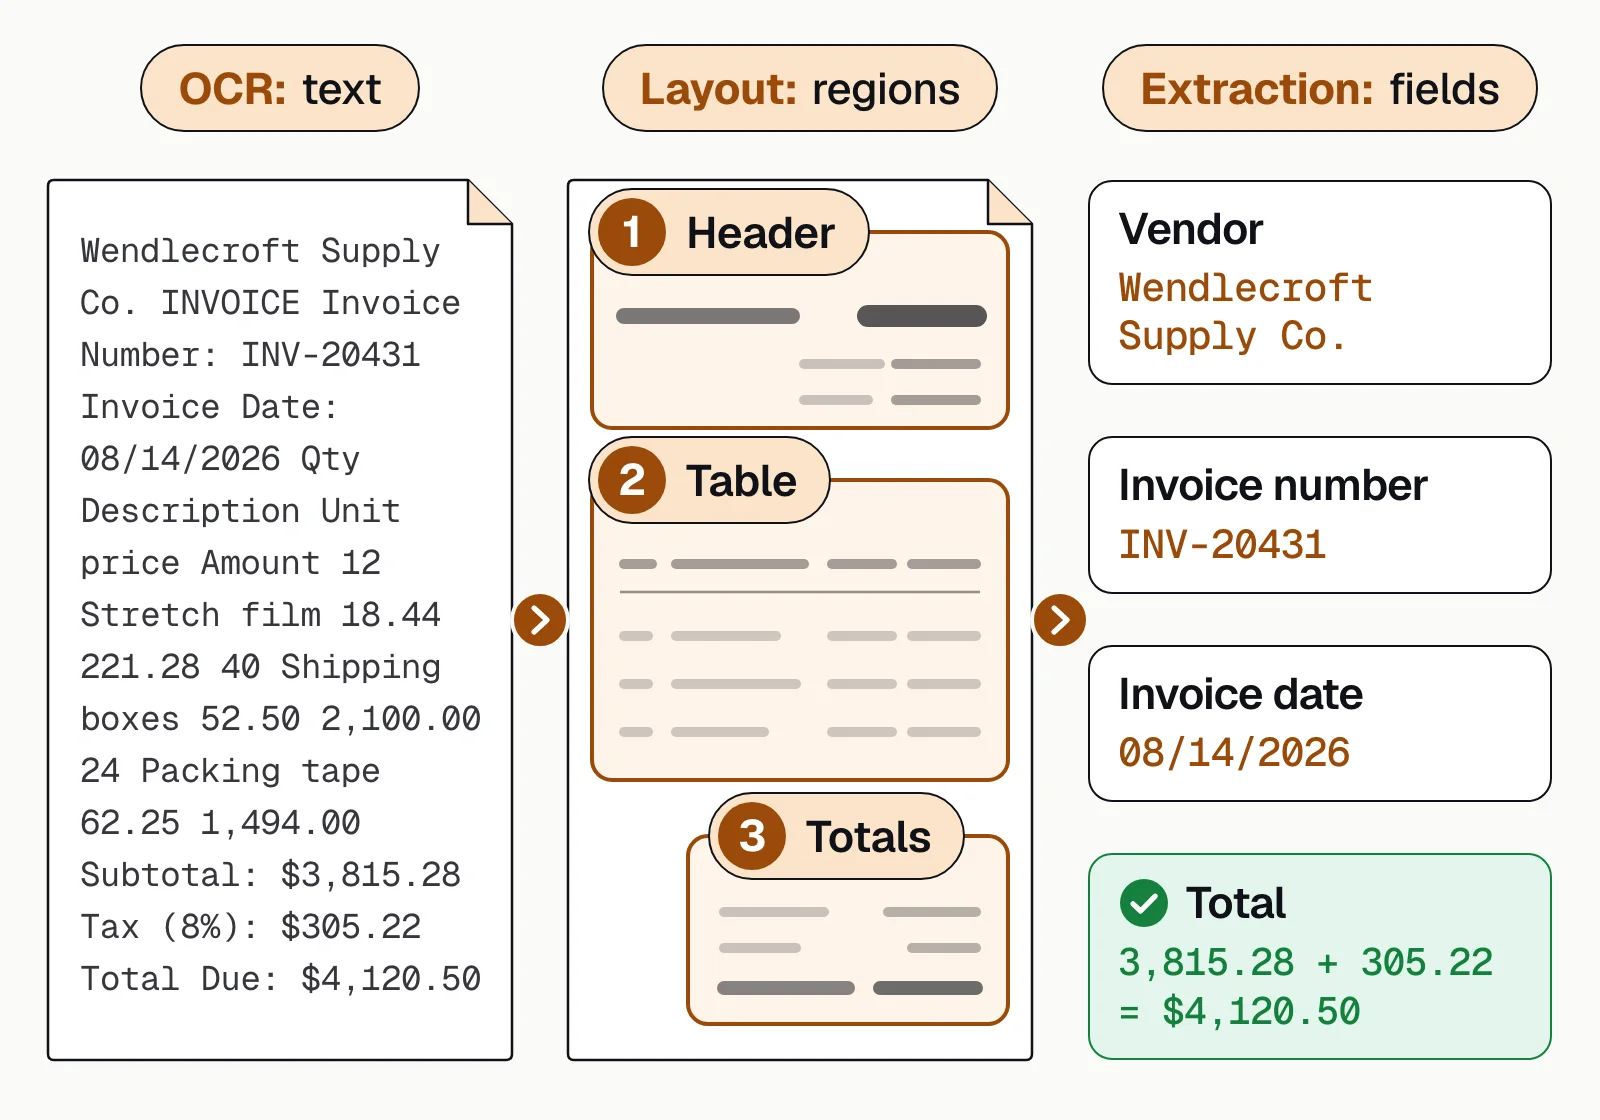
Extraction answers "what does the document say?" and leaves "what does it mean?" to analysis.
Document analysis vs data extraction: key differences
| Aspect | Data extraction | Document analysis |
|---|---|---|
| Question it answers | What exactly does the document say? | What does it mean for the question we're asking? |
| Output | Structured fields: JSON, CSV, spreadsheet or database rows | A decision, summary, classification, flag or research finding |
| Methods | OCR, templates and rules, machine learning and language models | Classification, comparison, rule checks and summaries; in research, coding and thematic analysis |
| Judgment | Low: find the value and copy it exactly | High: weigh documents, resolve conflicts, interpret |
| Who does it | Software, with a person checking values it's unsure of | Analysts, underwriters, reviewers and researchers |
| Example | Pull the deposits from three months of bank statements | Decide whether those deposits support the income on the application |
An old rule says that extraction works on structured sources, such as tables, and analysis works on unstructured ones, such as free text. That is no longer true for documents, because extraction now reads scans and handwriting as well as free text. The real difference is the output. Extraction produces values. Analysis produces meaning.
How extraction and analysis work together
In a document workflow, extraction comes first and analysis builds on it. A loan file is a typical example. Software sorts the documents by type and extracts the fields and transactions. It checks them, and the underwriter analyzes the result.
- Bank statements
- Pay stubs
- Tax returns
- IDs
- 01Classify each document
- 02Extract fields and tables
- 03Validate within and across documents
- 04Analyze and decide
Each step leaves less work for the next one. Once software classifies a document, it knows which fields to look for. Its validation checks find a balance that doesn't reconcile or a name that doesn't match the application, before anyone opens the file. The underwriter spends their time on the judgment call, not on retyping numbers.
Which one do you need?
What do you need from your documents?
Docsumo is an intelligent document processing (IDP) platform built for that last case. Its Document AI classifies and splits documents (Business plan). It also extracts fields and tables, with 99% field-level accuracy across 250+ document types. Cross-document validation checks documents against each other on the Enterprise plan. Fields the model is unsure about go to your reviewer with the source line highlighted.
Custom analysis, such as a summary or a calculation, is a workflow step you set up. It can be an AI step or your own Python code. Docsumo doesn't make the decision. Results go to your systems through the API and webhooks, or download to Excel.
We wouldn't pick tools for a shortlist by the name each one uses. Document AI, document intelligence and IDP are names for one category of software, and the tools under each name overlap. We'd run a few of your own documents through every tool on the list and compare what comes back.
Document analysis in qualitative research
In research, document analysis is a method of its own. It is also called documentary analysis. Researchers often use it alongside interviews and observation. Bowen (2009) defines it as a systematic procedure for reviewing or evaluating documents. Health policy researchers Dalglish, Khalid and McMahon set it out in four steps, which they call the READ approach.
- Ready your materialsSet the topic, the dates to include and where to search, so the set of documents fits the research question.
- Extract dataRecord what each document contains. A simple way is a spreadsheet with one row per document and one column per category. Categories range from title, author and date to the concepts in your question.
- Analyze dataApply a method to the whole set, such as policy analysis, discourse analysis or process tracing.
- Distill your findingsImprove the results by writing memos, making graphics and writing narratives. Stop when new documents show you nothing new.
Step 2 is data extraction by another name, which is why the two terms often appear together. Researchers code documents in a spreadsheet or in qualitative data analysis software such as NVivo, MAXQDA or ATLAS.ti. The method has weaknesses. A document may not be genuine, its author may have written it to push a view, or the records you have may not be typical. Researchers guard against them by triangulating, which means checking findings against other documents and other kinds of data.
What software reads and what people decide
Data extraction gets exact values out of documents. Document analysis decides what they mean. In business, extraction comes first and analysis uses its results. So when software does the extraction and its checks, people make only the decisions that need judgment. In research, extraction is one step of the analysis, done by hand or in coding software.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions
What is document analysis?
Document analysis is the systematic review of documents to answer a question. In business, that means classifying, summarizing, comparing or evaluating documents. Examples are contracts, statements and applications. In qualitative research, it's a method for reviewing documents as evidence, often alongside interviews or observation.
What is document analysis in qualitative research?
It's a research method, also called documentary analysis. Bowen (2009) defines it as a systematic procedure for reviewing or evaluating documents. Researchers use it to give context, generate questions, add to other research data, track change over time and corroborate other sources. The READ approach breaks it into four steps. They are to ready your materials, extract data, analyze data and distill your findings.
What is an example of document analysis?
A health policy researcher reviews a country's policies, field reports, program evaluations and news articles to trace how a program was adopted. A lender reviews three months of bank statements to decide whether the deposits support the income on a loan application. A history student examines a letter or poster from the period and uses it as evidence.
What is the difference between document analysis and content analysis?
Content analysis is one way to analyze documents. It codes what they say into categories, often counting how often each one appears. Document analysis is the wider method. It also covers choosing the documents, judging who wrote them and why, and interpreting them, often with other techniques alongside.
How is data extraction used in document processing?
It turns documents into data other systems can use. Software reads each page and finds the fields, such as an invoice number or each transaction on a statement. It sends the values to an ERP, a loan system or a spreadsheet, with checks along the way. A person reviews the values it's unsure of. See what data extraction is.
What tools are used for document analysis?
Researchers code documents in a spreadsheet or in qualitative data analysis software such as NVivo, MAXQDA or ATLAS.ti. Businesses that handle documents at volume use intelligent document processing (IDP) platforms. These classify the documents, extract the data and check it, so people review only the exceptions.
Sources
- Dalglish, Khalid and McMahon (2020): Document analysis in health policy research: the READ approach. Health Policy and Planning 35(10)
- Bowen (2009): Document Analysis as a Qualitative Research Method. Qualitative Research Journal 9(2)
- National Archives: Document analysis worksheets
- Lumivero: NVivo
- VERBI: MAXQDA
- ATLAS.ti
First published . Last updated .