The best AI data extraction software in 2026: 11 document extraction tools compared
For finance, lending, insurance and operations teams choosing a tool to pull data out of PDFs, scans and forms: how AI extraction differs from templates, and 11 tools compared on what they read, what they cost and who they suit.
Key takeaways
- AI data extraction software turns PDFs, scans and images into structured fields and tables, using machine learning and language models instead of a fixed template per layout.
- The tools fall into three groups: IDP platforms that add validation and workflow around extraction (Docsumo, ABBYY Vantage, Tungsten TotalAgility, Hyperscience, Rossum, Nanonets), cloud document AI APIs for developers (Google, AWS, Microsoft) and desktop and open-source tools (Adobe Acrobat Pro, Tesseract, Docling, Tabula).
- The biggest difference between tools isn't OCR quality. It's what happens after extraction: validation rules, a review queue for low-confidence fields, and integrations.
- Test every shortlisted tool on your own documents, including poor scans, multi-page tables, handwriting and new layouts, and ask how many samples a new document type needs.
- Web scraping and ETL tools extract data from websites and apps, not from documents, so they're left out of this list.
On this page
- What AI data extraction software does
- Template-based vs template-free extraction
- How we chose these tools
- The 11 best AI data extraction tools
- Document data extraction software compared
- What buyers overlook
- How to choose AI data extraction software
- Where the real differences show up
- Frequently asked questions
The best AI data extraction software depends on who will run it. Operations teams that need checked data from PDFs, scans and forms use an intelligent document processing (IDP) platform such as Docsumo, ABBYY Vantage or Hyperscience. Developers building their own pipeline start with a cloud API such as Google Document AI, Amazon Textract or Azure Document Intelligence, and teams with no budget use open-source tools such as Tesseract and Docling.
Which team are you?
What AI data extraction software does#
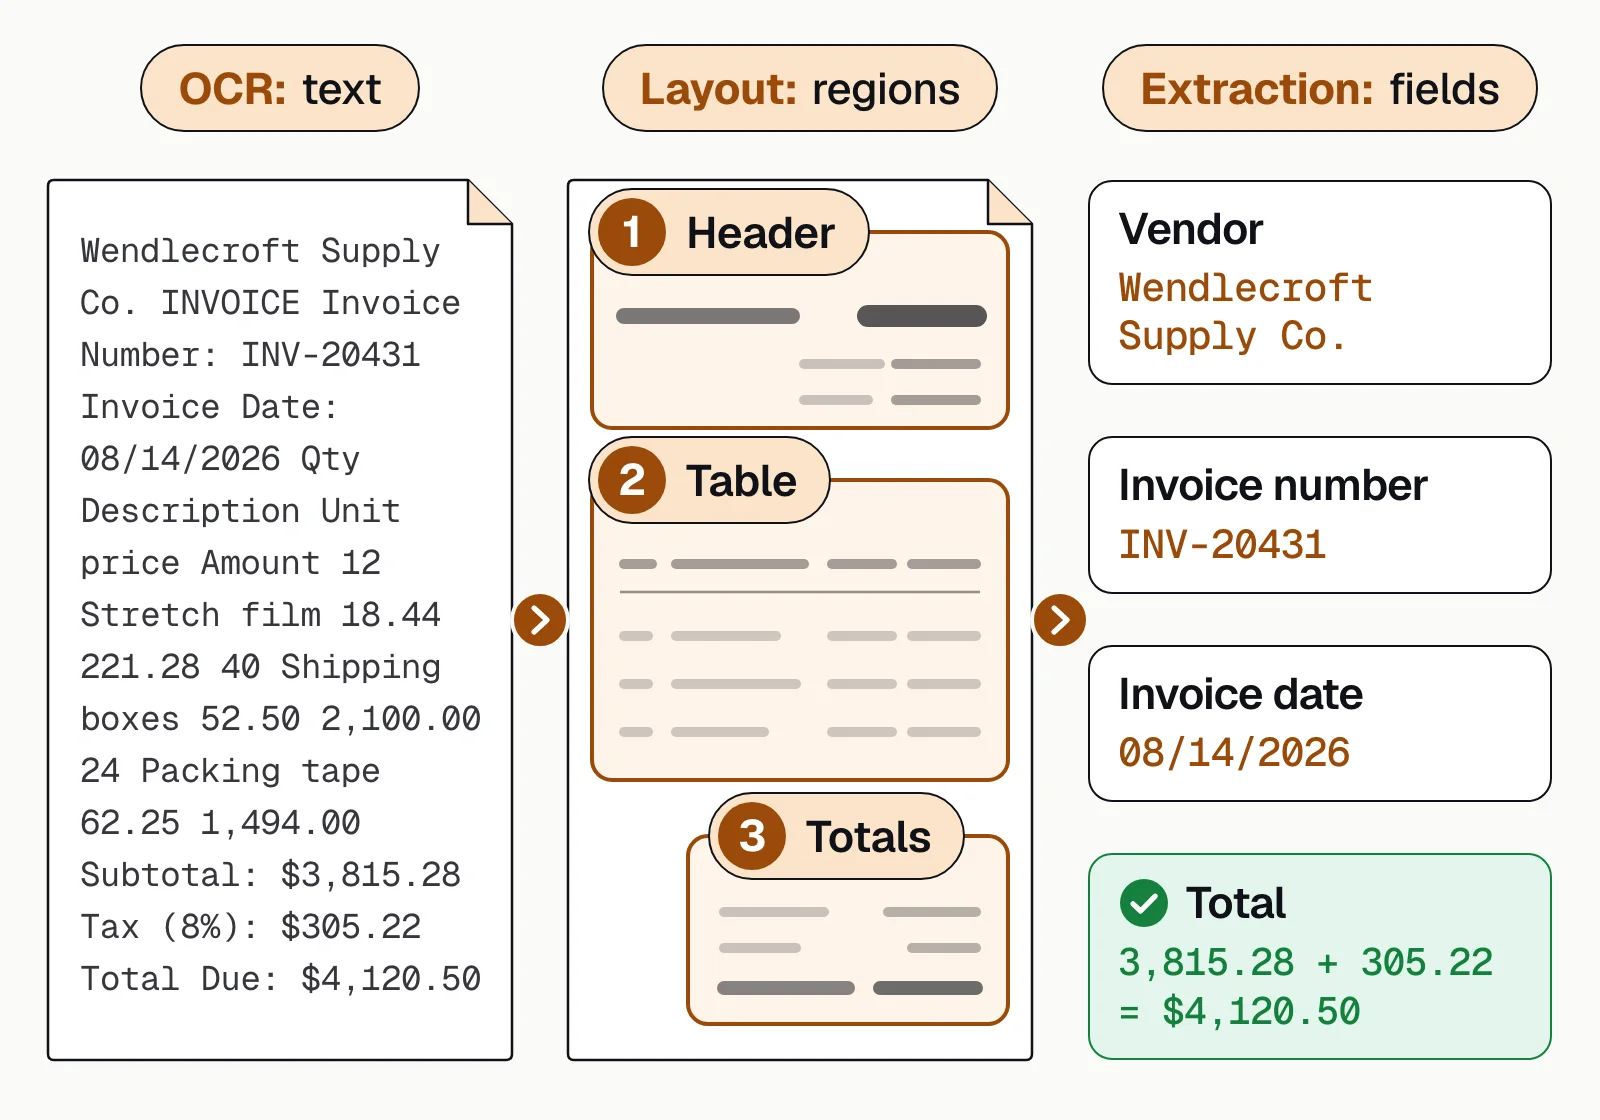
AI data extraction software turns unstructured and semi-structured documents into structured data. Every tool reads the page; they differ in what happens around that step.
- Uploads
- API
- 01Classify
- 02Extract
- 03Validate
- 04Review
OCR is only the first layer: it turns an image of text into characters, but it doesn't know which number is the total. Our guide to AI document extraction walks through each stage.
Template-based vs template-free extraction#
Older capture tools need a template for each layout, often one per supplier, built from fixed zones or rules, such as reading the total as the number to the right of the word Total. That works well on one stable form, but every new supplier or redesign needs a new template to maintain.
Template-free tools work differently. Machine learning models trained on labeled examples find the invoice total wherever it sits on the page, which suits common documents that arrive in many layouts, such as invoices and bank statements. LLM-based extraction goes further, returning whatever fields you ask for from a plain list or a few samples, which fits long-tail and less structured documents a trained model has never seen.
LLMs can return a plausible value that isn't on the page, so production tools pair them with confidence scores, validation rules and human review. Docsumo reads characters with OCR and uses LLMs to structure the output, so it isn't limited to its pre-trained models.
How we chose these tools#
We included tools that extract data from documents and are sold or maintained in 2026; web scraping and ETL tools, which pull data from websites and apps, are left out. Descriptions come from each vendor's own site, checked in September 2026, with links in the sources. Docsumo is our product, so it's first, with a plain note on what it doesn't do.
The 11 best AI data extraction tools#
IDP platforms
Platforms that wrap extraction in classification, validation and workflow, so an operations team can run them.
1. Docsumo
IDP platformOur product- Reads
- Any business document; pre-trained models for 250+ types, including bank statements, invoices and ACORD forms
- Output
- Fields and tables through an API and webhooks
- Pricing
- A free 14-day trial for up to 1,000 pages; Business and Enterprise plans are quoted
- 99%field-level accuracy
- 95%+of documents processed straight through, without manual review
- 250+document types with pre-trained models
2. ABBYY Vantage
IDP platform- Reads
- Structured and unstructured documents, including handwriting, barcodes and checkboxes
- Output
- REST API, human-in-the-loop review and RPA connectors
- Pricing
- Not published
3. Tungsten TotalAgility
IDP platform- Reads
- Document types aren't itemized on the product page
- Output
- Workflow orchestration and business rule validators
- Pricing
- Not published
4. Hyperscience
IDP platform- Reads
- Forms, invoices, contracts, handwriting including cursive, and long documents of up to 200 pages
- Output
- API-first, with integration blocks for SAP, Salesforce and Microsoft 365
- Pricing
- Not published; volume-based
5. Rossum
IDP platform- Reads
- Invoices, purchase and sales orders, bills of lading and customs documents
- Output
- Validation screen and API; ERP integrations on higher plans
- Pricing
- Starter from $18,000 a year; 14-day free trial (published)
6. Nanonets
IDP platform- Reads
- Invoices, purchase orders, remittances, W-9s, insurance certificates and scans
- Output
- API and ERP connectors; edge cases go to Slack, Teams or email for review
- Pricing
- $50 in free credits, then from $100 a month (published)
Cloud document AI APIs
Developer services priced per page. They return text, tables and fields as JSON; you build the validation, review screen and integrations.
7. Google Document AI
Cloud API- Reads
- PDFs and images, with printed text in 200+ languages; parsers for invoices, bank statements, pay slips, W-2s and IDs
- Output
- JSON with text, tables and entities
- Pricing
- OCR $1.50 per 1,000 pages; Form Parser $30 per 1,000 pages (published)
8. Amazon Textract
Cloud API- Reads
- PNG, JPEG, TIFF and PDF; handwriting in English only
- Output
- JSON with a confidence score for each item; Amazon Augmented AI (A2I), AWS's separate human review service, is no longer open to new customers
- Pricing
- Text $1.50, forms $50 per 1,000 pages (published, US West)
9. Azure Document Intelligence
Cloud API- Reads
- Invoices, receipts, IDs, pay stubs, bank statements, checks and US mortgage and tax forms
- Output
- JSON through the API and SDKs; containers available
- Pricing
- Read $1.50, prebuilt $10 per 1,000 pages; 500 free pages a month (published)
Desktop and free tools
10. Adobe Acrobat Pro
Desktop app- Reads
- Scanned paper and image-only PDFs
- Output
- Searchable PDFs; Word, Excel and PowerPoint files
- Pricing
- $19.99 a month on an annual plan (published)
11. Tesseract, Docling and Tabula
Open source- Pricing
- Free (Apache 2.0 or MIT license)
Document data extraction software compared#
"Human review" means the product sends uncertain results to a person; "Build your own" means you add that step yourself.
| Tool | Best for | Deployment | Human review |
|---|---|---|---|
| IDP platforms6 tools | |||
| DocsumoOur product | Lending, insurance, AP | Cloud only | Yes, per-field thresholds |
| ABBYY Vantage | Enterprises with RPA programs | Cloud, on-premises, private cloud | Yes |
| Tungsten TotalAgility | End-to-end process automation | Public or private cloud, on-premises | Not described |
| Hyperscience | Government, regulated enterprises | Cloud, on-premises, air-gapped | Yes |
| Rossum | AP and logistics, Coupa customers | Cloud | Yes, validation screen |
| Nanonets | AP and finance workflows | Cloud; VPC or on-premises (Enterprise) | Yes, via Slack, Teams or email |
| Cloud APIs3 tools | |||
| Google Document AI | Google Cloud developers | Google Cloud | Build your own |
| Amazon Textract | AWS developers | AWS | Build your own (A2I closed to new customers) |
| Azure Document Intelligence | Azure developers | Azure, containers | Build your own |
| Desktop and free tools2 tools | |||
| Adobe Acrobat Pro | Occasional PDF conversions | Desktop, web | No |
| Tesseract, Docling, Tabula | Building your own pipeline | Self-hosted | Build your own |
What buyers overlook#
Five things rarely make it onto an RFP but decide whether a rollout works.
- Template upkeep and new document typesTemplates break when a supplier redesigns its invoice. For template-free tools, ask how many labeled samples a new document type needs, and multiply by the new types you expect each year.
- Accuracy drift after go-liveAsk how the vendor tracks field-level accuracy over time and how retraining works.
- How exceptions are reviewedA screen that shows only the unsure fields, next to their place on the page, saves more time than a slightly higher accuracy figure.
- Cross-document checksSingle-document accuracy won't catch a pay stub whose income disagrees with the bank statement. If you review applications as a set, ask whether the tool compares documents.
- Integration depth, not countA listed ERP connector may only attach the PDF to a record. Ask for a demo of your exact workflow.
How to choose AI data extraction software#
We'd judge a tool by what a person still has to fix, not by the number on its homepage. A vendor's accuracy figure is measured on its own test set, in its own way, so the score that matters is the one you get from running your worst documents through it and counting the corrections your reviewers make.
- List your documents and volumesPre-trained models for your document types save months; a tool built for invoices may not handle bank statements.
- Decide who will run itOperations staff need a review screen; engineers may only need an API.
- Test on your own filesSend 50 to 200 real documents, including poor scans, handwriting, multi-page tables and new layouts, and measure field-level accuracy.
- Check the validation layerCan it check totals, match master data and compare the documents in an application?
- Check integrations and securityAn API and webhooks into your systems; SOC 2 Type 2 and, where relevant, HIPAA.
- Compare total costPer-page fees look cheap until you add the engineering and review time around them.
For the methods underneath these tools, see data extraction techniques and IDP vs OCR.
Where the real differences show up#
Every tool here can read a clean invoice. The differences show up on hard documents and in how much you build around them. Cloud APIs and open-source libraries are building blocks. IDP platforms add the validation, review and integrations that make extracted text usable, and Docsumo fits lending, insurance and AP teams that want that in the cloud.
Book a demo and bring a few of your own documents, or start a free trial.
Frequently asked questions#
What is the best software for extracting data from documents?
It depends on who will run it. Operations teams processing financial or insurance documents usually want an IDP platform with review and validation, such as Docsumo, ABBYY Vantage or Hyperscience. Developers building their own pipeline often start with Google Document AI, Amazon Textract or Azure Document Intelligence.
Is there free document data extraction software?
Yes. Tesseract (OCR), Docling (layout and table parsing) and Tabula (tables in text-based PDFs) are free and open source, but they leave field mapping, validation and review to you. The cloud APIs have free tiers, and Docsumo has a free 14-day trial for up to 1,000 pages.
What is the difference between OCR and AI data extraction?
OCR converts an image of text into characters. AI data extraction also understands structure and context, so it finds specific fields such as an invoice total or an account number, keeps table rows together and returns structured data even when layouts change.
Do data extraction tools still need templates?
Most modern tools are template-free, sometimes called template-less: they find fields from context, so a new supplier's invoice layout doesn't need a new template. Some need a few labeled samples for a new document type. Older template-based tools need zones or rules for every layout.
Is there an SDK for template extraction?
Yes. Azure Document Intelligence has SDKs for C#, Python, Java and JavaScript, with custom template models for fixed layouts and custom neural models for mixed documents, and ABBYY sells FlexiCapture as an SDK for building capture into your own software. Open-source tools such as Tesseract and Docling run inside your own code, and Docsumo connects to your systems through its API and webhooks.
How much does document data extraction software cost?
Basic OCR costs $1.50 per 1,000 pages on Google, AWS and Azure, and form, table or custom field extraction $10 to $50 per 1,000 pages. Most IDP platforms quote prices instead of publishing them, and open-source tools are free but need engineering time. Docsumo has a free 14-day trial for up to 1,000 pages; see pricing.
Sources
- Google Cloud: Document AI overview
- Google Cloud: Document AI pricing
- AWS: Amazon Textract features
- AWS: Amazon Textract pricing
- AWS: Amazon Augmented AI (human review for Textract)
- AWS: Using Amazon Augmented AI for human review (not open to new customers)
- Microsoft Learn: What is Azure Document Intelligence in Foundry Tools?
- Microsoft: Azure Document Intelligence pricing
- ABBYY: Vantage
- ABBYY: FlexiCapture
- Tungsten Automation: TotalAgility
- Hyperscience: Hypercell platform
- Rossum: pricing
- Rossum: Coupa acquires Rossum (May 12, 2026)
- Nanonets: home page
- Nanonets: pricing
- Adobe: Acrobat pricing
- Adobe: Acrobat Pro
- GitHub: Tesseract OCR
- GitHub: Docling
- GitHub: Tabula
First published . Last updated .