Data extraction vs data ingestion: the difference, and how ETL and integration fit
For data, operations and finance teams: what extraction and ingestion each do, how they compare with ETL and data integration, and where documents fit in.
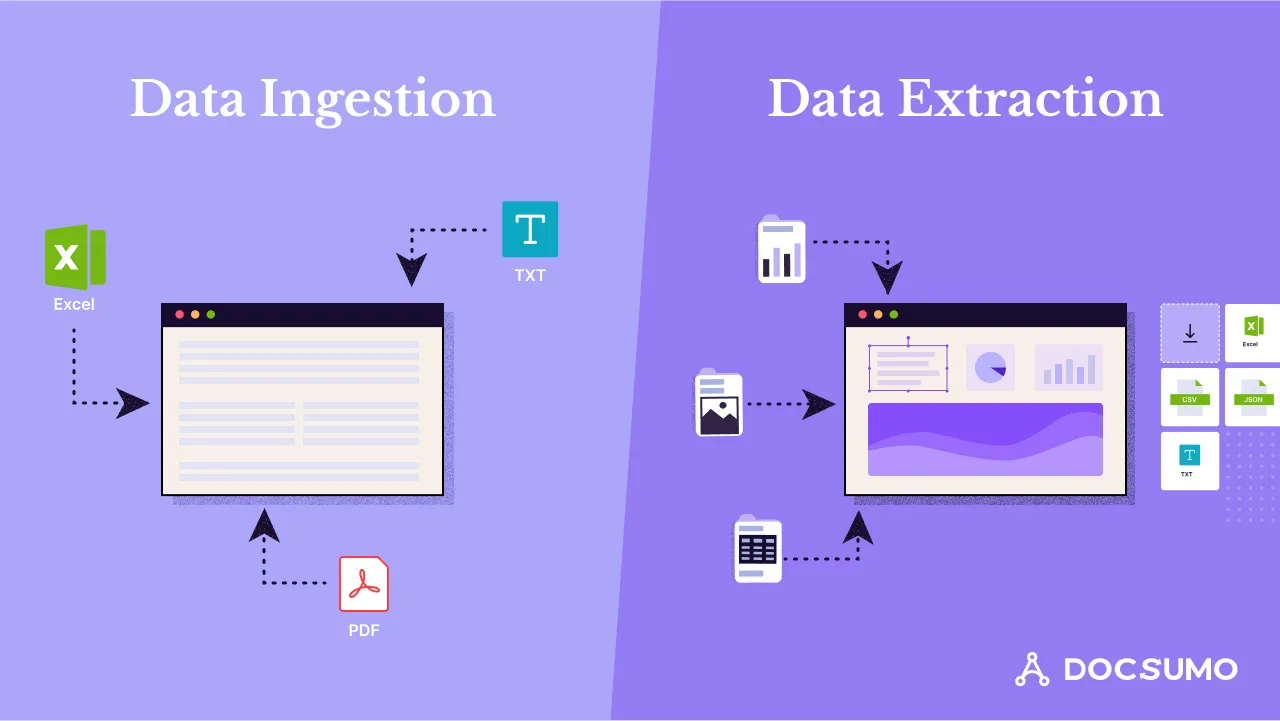
Key takeaways
- Data extraction pulls specific data out of a source, such as fields from an invoice or rows from a database table.
- Data ingestion moves data from its sources into a destination, such as a data warehouse, data lake or business system, in batches or as a stream.
- ETL (extract, transform, load) is one way to run ingestion: data is extracted, transformed, then loaded. Data integration goes further and combines sources into one consistent view.
- Extraction usually comes first. For documents such as PDFs and scans, extraction is the hard part, because the data has to be read before it can be loaded anywhere.
On this page
Data extraction pulls specific data out of a source, such as the total from an invoice or selected rows from a database. Data ingestion moves data from its sources into a destination, such as a data warehouse or business system, where it can be stored and analyzed. Extraction answers "what do we need from this source?"; ingestion answers "how does it get where it's used?", and in most pipelines extraction comes first.
| Aspect | Data extraction | Data ingestion |
|---|---|---|
| Purpose | Pull specific data out of a source | Move data into a destination system |
| Scope | Selected fields, records or tables | Whole datasets from one or many sources |
| Timing | On demand or scheduled | Batch, micro-batch or real-time streaming |
| Typical tools | Database queries, APIs, web scraping, OCR and document AI | ETL and ELT tools, streaming platforms, cloud data pipelines |
| Output | Structured values: JSON, CSV, Excel or database rows | Data landed in a warehouse, lake or application |
This guide covers what each process does, how both relate to ETL and data integration, and when you need which.
What is data extraction?#
Data extraction is collecting specific data from a source so it can be used somewhere else. The source can be a database, an application, a web page or a document. It's targeted: you decide which fields or records you need and leave the rest.
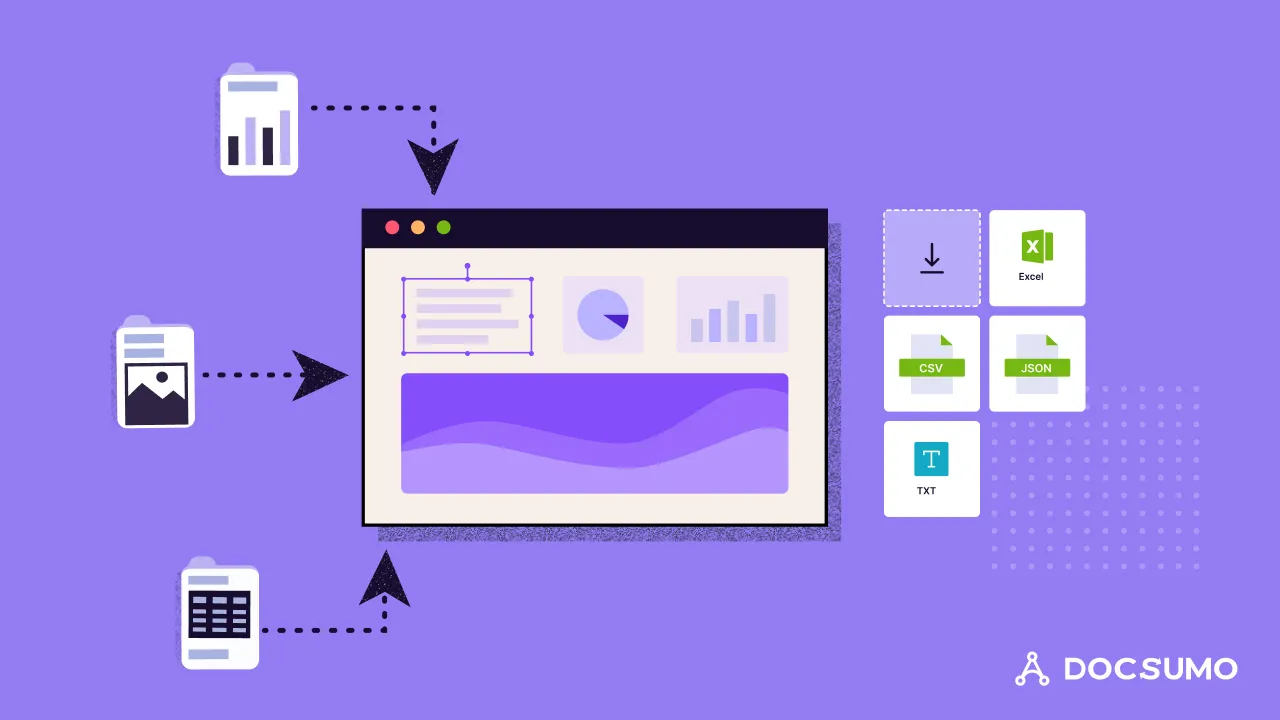
From databases and apps
A query or API call returns selected records, such as last month's orders from an ERP.From web pages
Scraping tools read prices, listings or other values from pages that have no API.From documents
OCR and document AI read PDFs, scans and photos, and return named fields and tables: invoice totals, bank transactions, policy limits.
Structured sources are easy to extract from: the data already sits in named columns. Documents are harder, because the same field appears in a different place on every layout, and scans have to be read before anything can be pulled out.
What is data ingestion?#
Data ingestion is collecting data from different sources and making it available for storage, processing and analysis. The data lands in a central system, usually a data warehouse, a data lake or an application, and is often cleaned and standardized on the way. See the full data ingestion guide for the steps and tools.
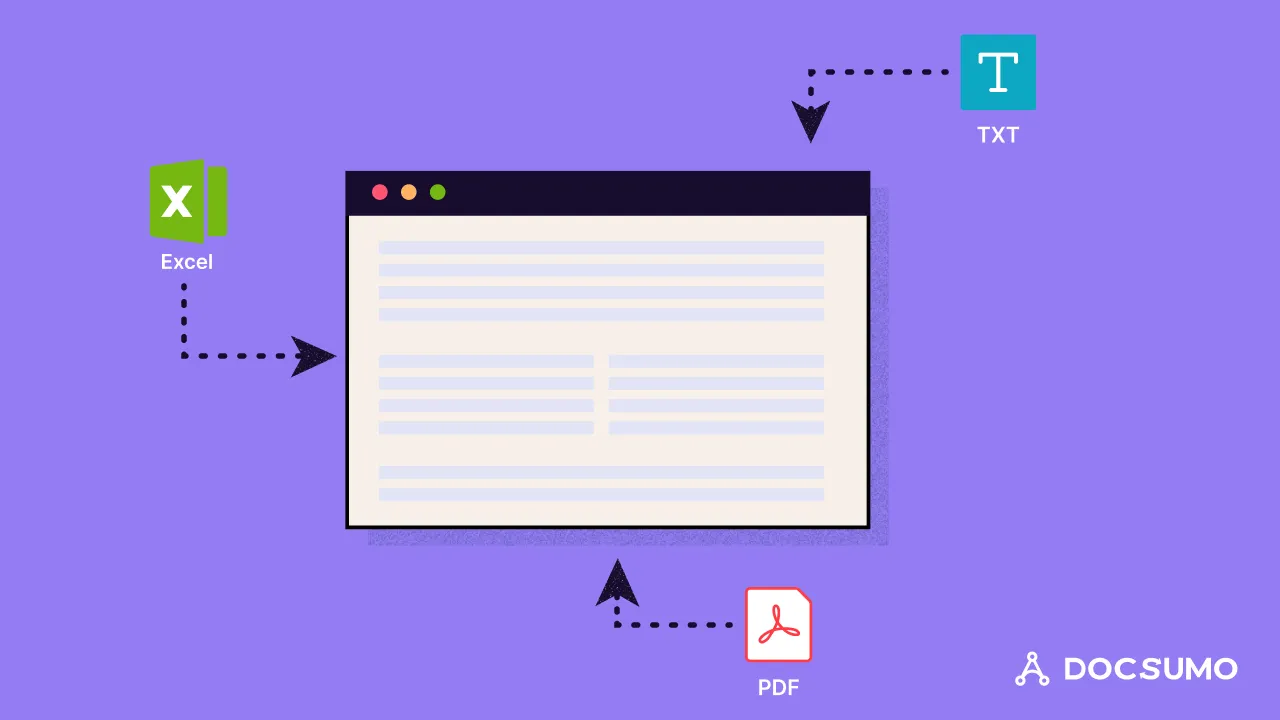
Batch
Data collects over a period, such as an hour or a day, and loads in one run. Simple and reliable, but not current.Real-time (streaming)
Each record loads as it's created, for work that can't wait, such as payments or monitoring.Micro-batch
Small, frequent batches: close to real time without the cost of a full streaming setup.
How extraction and ingestion work together#
In most pipelines they're steps of one flow rather than alternatives. Extraction gets the data out of each source, ingestion loads it, and transformation cleans it before or after loading.
- Databases and apps
- PDFs and scans
- Email attachments
- 01Extract the data
- 02Validate it
- 03Load it
- 04Transform it
For documents, the extract and validate steps carry most of the work. An invoice has to be read, its fields checked (does the total equal the line items?) and uncertain values reviewed before it's loaded; otherwise the errors travel downstream.
Data ingestion vs ETL and data integration#
The terms overlap, so it helps to place each one.
ETL (extract, transform, load)
One way to run ingestion: data is extracted, cleaned and reshaped, then loaded. The "extract" step is data extraction.ELT (extract, load, transform)
Raw data loads first and is transformed inside the destination, common with cloud warehouses.Data integration
Goes further than ingestion: it combines and standardizes several sources into one consistent view, such as a single customer record.Data acquisition
Getting the data in the first place: collecting it, buying it or receiving it from customers. Ingestion loads what was acquired.
So data ingestion vs ETL isn't a choice between two tools: ETL is a pattern for ingestion. And ingestion is usually one part of a data integration project.
When to focus on extraction, ingestion or both#
What's your situation?
Where document extraction fits#
Much business data still arrives as documents: invoices, bank statements, forms and claims. Before that data can be ingested anywhere, something has to read it.
Docsumo is an intelligent document processing platform: document AI reads PDFs, scans and email attachments, validates the fields and sends values it's unsure about to a person for review. The results go to your warehouse or business systems through API and webhooks, or download to Excel. It isn't a general data pipeline or streaming tool: it handles the extraction side, and your ingestion tools load what it returns. For document types, see invoice extraction and bank statement extraction.
The bottom line#
Data extraction gets specific data out of a source; data ingestion gets data into the system where it's used. ETL is one way to ingest, and data integration builds on ingestion to combine sources. When your sources are documents, extraction is the hard part, and the step worth automating first.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions#
What is the difference between data extraction and data ingestion?
Data extraction pulls specific data out of a source, such as fields from a document or records from a database. Data ingestion moves data from one or more sources into a destination system where it can be stored and analyzed. Extraction is often the first step of an ingestion pipeline.
Is data ingestion the same as ETL?
No. Data ingestion is the broad process of getting data into a destination. ETL (extract, transform, load) is one method of doing it, where data is cleaned and reshaped before it's loaded. In ELT, raw data is loaded first and transformed inside the destination.
What is the difference between data ingestion and data integration?
Ingestion is the entry point: it brings data from one or more sources into a system. Data integration goes further, combining and standardizing data from several sources so they can be used together, for example one customer record built from a CRM, billing and support data.
What is the opposite of data ingestion?
Moving data out of a system rather than into it, usually called data egress or data export. A report exported from a warehouse to a spreadsheet, or records sent from one system to another through an API, are examples.
What is an example of data ingestion?
A nightly batch job that loads the day's sales from a point-of-sale system into a data warehouse, or a stream that loads payment events as they happen. When the source is documents, extraction reads each invoice or statement first and ingestion loads the fields.
What is the difference between data acquisition and data ingestion?
Data acquisition is getting data in the first place, such as collecting it from sensors, buying a dataset or receiving documents from customers. Ingestion is loading that data into the system where it will be stored and used.
Sources
First published . Last updated .