How to extract data from PDF files: 5 methods, from copy-paste to automated AI extraction
For operations and data teams that get invoices, statements and forms as PDFs every day. See the 5 ways to get the data out, which one fits your volume, and the checks that keep the numbers right.
Key takeaways
- A PDF stores characters and where they sit on the page, not fields. Software has to work out which number is the account number and which is the amount due.
- The 5 methods are manual entry, PDF converters, table extraction tools, rule-based templates and AI extraction. Your volume and the number of layouts decide which one fits.
- Scanned PDFs need OCR (optical character recognition) before any extraction, because each page is only a picture. A fillable PDF form is the easy case, since each answer sits in a named field.
- Excel for Microsoft 365 on Windows imports tables from a PDF (Data > Get Data > From File > From PDF). Google Sheets can't open PDFs, so get the tables into Excel or CSV first.
- Automated PDF data extraction has to check its own output. Totals should add up. The software scores how sure it is of each value, and values with a low confidence score should go to a person.
On this page
- Why PDF data extraction is hard
- First, check what kind of PDF you have
- 5 ways to extract data from PDFs
- How to extract data from PDF forms
- How to convert PDF data to Excel or Google Sheets
- Common PDF extraction failures and fixes
- How automated PDF data extraction works
- One utility bill, from inbox to spreadsheet
- Checks to run on extracted PDF data
- Which PDFs to automate first
- Frequently asked questions
You can extract data from a PDF by hand, with a converter or table tool, with templates, or with AI. Hand-copying or converting is fine for a few files. Invoices, statements and forms that arrive every day in many layouts need automated AI extraction with checks.
| Field | Extracted value | Confidence |
|---|---|---|
| Provider | Riverbend Electric & Gas | |
| Customer name | Maple Court Apartments LLC | |
| Account number | 3108-5572-40 | |
| Service address | 2150 Maple Ct, Columbus, OH 43215 | |
| Billing period | 2026-08-05 → 2026-09-03 | |
| Issue and due date | 2026-09-08 · 2026-09-29 |
| Field | Extracted value | Confidence |
|---|---|---|
| Previous balance | 1,742.30 | |
| Payment received | −1,742.30 | |
| Charges before tax | 1,719.86 | |
| Taxes and fees | 98.89 | |
| Current charges | 1,818.75 | |
| Total amount due | 1,818.75 |
| Field | Extracted value | Confidence |
|---|---|---|
| E-5520871 · electric | 9,420 kWh · 38.6 kW demand | |
| E-5520904 · electric | 1,080 kWh | |
| G-3317265 · gas | 194 CCF | |
| Reads · E-5520871 | 48,210 → 57,630 | |
| Tariff · E-5520871 | GS-2 General Service | |
| Supply rate · E-5520871 | $0.0912 / kWh |
Why PDF data extraction is hard#
PDF was built to make a page look the same everywhere, not to make its data reusable. It stores characters and their positions on the page. Nothing in the file says "this is the amount due".
Layouts vary
Every vendor and bank lays out its documents differently.Scans have no text
A scanned PDF is a picture of the page. Nothing can be copied until OCR reads it.Structure is complex
Pages have several columns, nested tables, and tables that continue onto the next page.Volume breaks manual fixes
A process that works for 10 files a week breaks at 10,000.
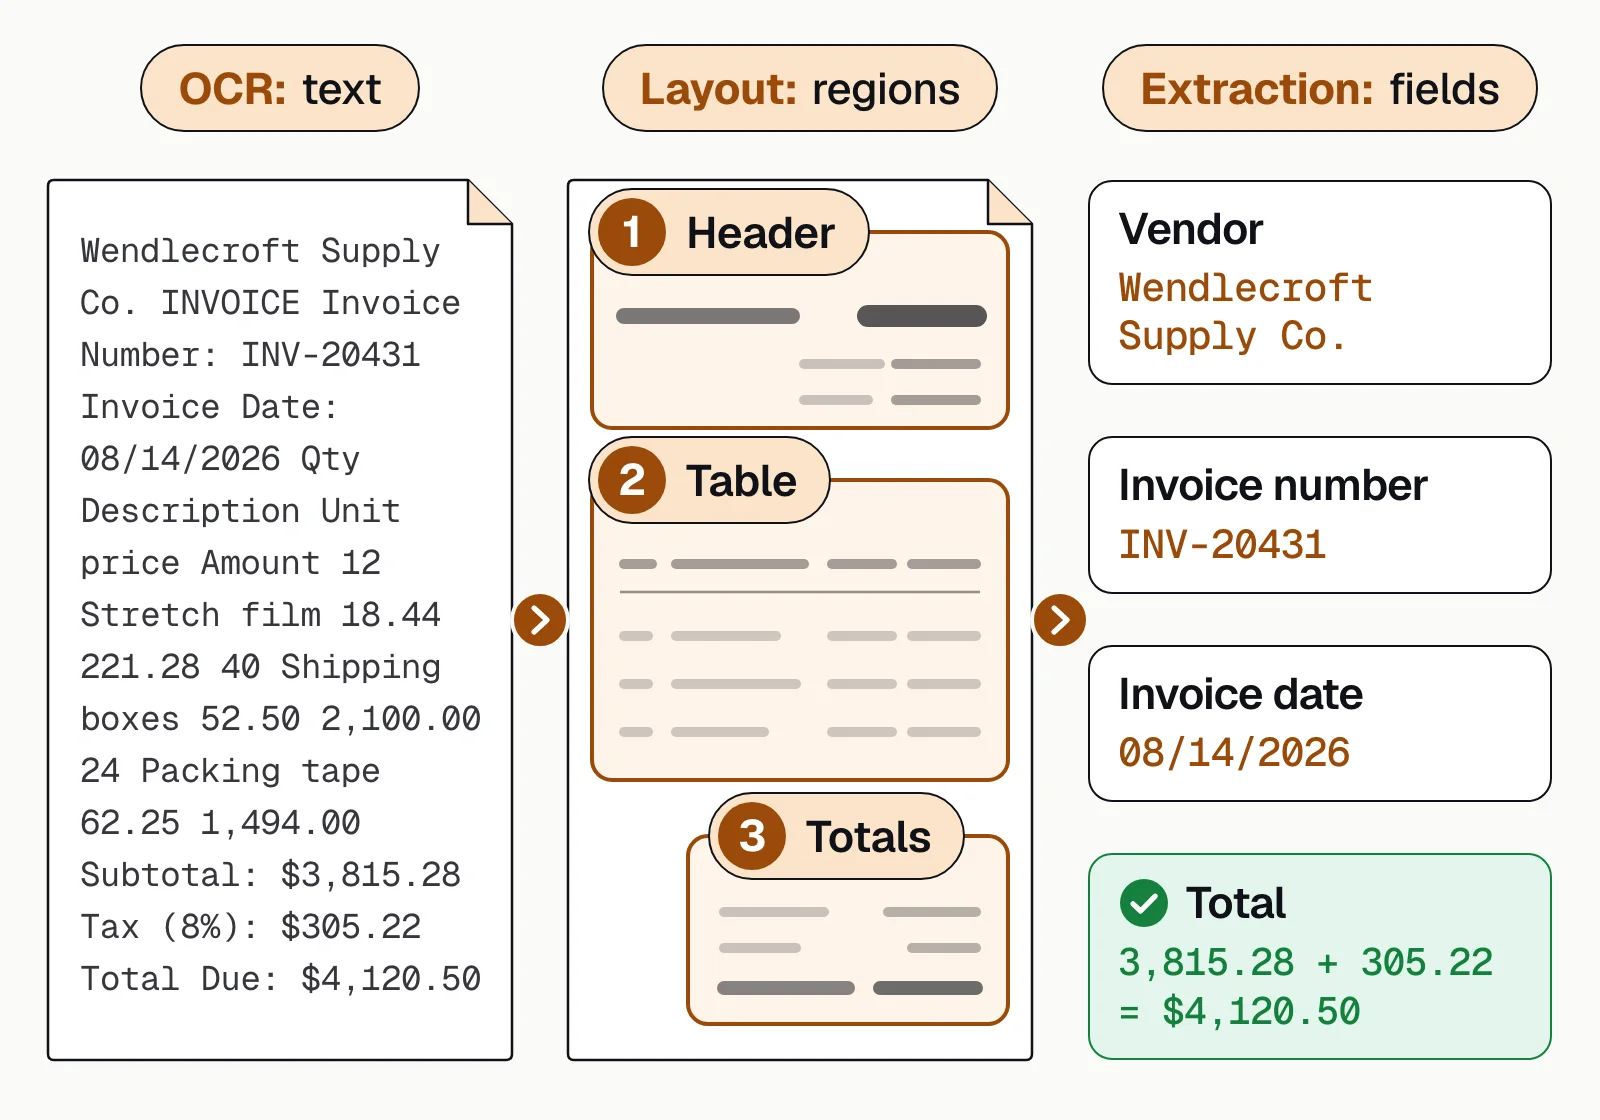
A basic PDF parser returns the page's text in rough reading order, with nothing to say which value is which. Two more steps fix that. Layout analysis finds the parts of the page, such as the header, tables and totals. Extraction then puts a name on every value, such as "amount due". The result is structured data.
First, check what kind of PDF you have#
Try selecting the text in a PDF viewer. What happens tells you the first step.
| PDF type | How to tell | First step |
|---|---|---|
| Text-based (native) | Text selects and copies cleanly | Copy the text stored in the file (its text layer); no OCR needed |
| Scanned | Nothing selects: the page is an image | Straighten and clean the page, then run OCR |
| Searchable scan | Text selects, but may copy with errors | Use the text layer; run OCR again where it's wrong |
| Fillable form | Fields you can click and type in | Read the field values directly (see PDF forms below) |
To make a scanned PDF searchable, or to turn it into an editable Word file, a desktop OCR app is enough. See the best OCR software. Docsumo isn't a desktop tool for editing PDFs or making searchable files. It's an intelligent document processing (IDP) platform that extracts and checks the data in your PDFs. It reads forms and can fill them out too.
5 ways to extract data from PDFs#
How many PDFs, and how varied?
| Method | Works on | Accuracy | Effort at scale | Best for |
|---|---|---|---|---|
| Manual data entry | Anything | Varies with fatigue | High | A few documents a week |
| PDF converters | Text-based PDFs with simple layouts | Good on clean files; loses structure on complex ones | Medium (cleanup) | One-off conversions |
| Table extraction tools | Text-based PDFs with clear tables | Good on ruled tables | Medium | Statements and reports with regular tables |
| Rule-based templates | Fixed, known layouts | High on the layouts you built | High (a template per layout) | One form from one source |
| AI-based extraction | Any layout, text-based or scanned | High, with confidence scores | Low | Recurring documents in many layouts |
1. Manual data entry
Someone reads each PDF and types the values in. It takes no setup, but it's slow and error-prone at volume.
2. PDF converters
Adobe Acrobat and similar tools convert a whole PDF to Excel or Word. Acrobat can put each table, each page or the whole document on its own worksheet. Complex layouts often come out with split cells and merged columns, so someone still has to tidy the sheet.
3. PDF scraping and table extraction tools
Free, open-source tools scrape a PDF's tables into rows and columns. Two of them, pdfplumber and Camelot, are Python libraries. Tabula is an app with a simple web interface, and tabula-java is the library behind it. Tabula's README says the app is unlikely to see updates soon, while tabula-java still gets occasional fixes.
Most of these tools need a text-based PDF. Tabula works only on text-based PDFs, and pdfplumber works best on them too. Camelot reads scans only with its optional ML and OCR add-ons.
This pulls the transactions from a text-based bank statement (tested on Python 3.11 with pdfplumber 0.11.10; pip install pdfplumber).
import pdfplumber

with pdfplumber.open("statement.pdf") as pdf:
    for page in pdf.pages:
        for table in page.extract_tables():
            header, *rows = table
            for row in rows:
                print(dict(zip(header, row)))
Output:
{'Date': '07/02/2026', 'Description': 'Payroll deposit', 'Amount': '2,450.00'}
{'Date': '07/05/2026', 'Description': 'Rent payment', 'Amount': '-1,800.00'}
{'Date': '07/19/2026', 'Description': 'Card purchase', 'Amount': '-86.40'}
It works because the table has ruling lines and the PDF is text-based. For scans and tables that run across pages, see table extraction from PDF.
4. Rule-based templates
A template reads each field from a fixed spot on a known layout, such as the value to the right of "Total Due". Every new layout needs a new template. See zonal OCR.
5. AI PDF data extraction
AI models trained on many examples find fields from the text, the layout and visual cues, so a new layout usually needs no setup. They read scans, join tables that run across pages and give every value a confidence score. A person checks only the values the model is unsure about. Our guide to AI data extraction explains how these models work.
Our take. Don't pick a tool by what its vendor calls it. Document AI, document intelligence and IDP are names for one category of software. Our advice is to take two or three candidates and run each one on the same batch of your own PDFs. Keep the one that gets your fields right with the least setup.
How to extract data from PDF forms#
How you get data out of a PDF form depends on where the answers are stored. In a fillable form, each answer sits in a named field. A flattened form has been saved so its fields can't be clicked any more. In a flattened, printed or scanned form, the answers are part of the page itself.
| Form type | How to tell | How to get the data |
|---|---|---|
| Fillable | You can click a field and type in it | Read the field values directly, with Acrobat or a library such as pypdf |
| Flattened | It looks filled in, but nothing is clickable | Read the page text, then pair each label with its value |
| Scanned or faxed | Nothing selects | Run OCR, then pair each label with its value |
| Handwritten | The answers are written by hand | Use OCR that reads handwriting, and have a person check unclear values |
Adobe Acrobat gets the answers out of fillable forms without code. To save one form's answers, open Prepare a form and choose Options > Export data. Acrobat saves them as FDF, XFDF, XML or TXT. To put many filled forms into one spreadsheet, choose Options > Merge data files into spreadsheet in the same panel.
In Python, pypdf reads a form's text fields in a few lines (tested on Python 3.11 with pypdf 6.19; pip install pypdf).
from pypdf import PdfReader

reader = PdfReader("vendor-form.pdf")
print(reader.get_form_text_fields())
Output:
{'vendor_name': 'Riverbend Electric & Gas', 'payment_terms': 'Net 30', 'remit_method': 'ACH'}
On a flattened copy of the same form, the code returns an empty result. The answers are still on the page. But in our copy, the page text lists the three labels first and the three values after them. Nothing says which value belongs to which label.
Pairing each label with its value is called key-value pair extraction. Scanned and handwritten forms need OCR first, as our guide to OCR form processing explains.
Docsumo reads handwritten text. When one PDF holds a stack of tax forms, it sorts the pages by form and extracts each box and line. See IRS tax forms and ACORD forms.
How to convert PDF data to Excel or Google Sheets#
Excel can pull tables straight from a PDF. Google Sheets can't, so the route depends on where the data has to go.
| Destination | How | Good to know |
|---|---|---|
| Excel, one file | In Excel for Microsoft 365 on Windows, choose Data > Get Data > From File > From PDF, then pick the tables | You get whole tables, and similar tables on consecutive pages are joined by default. Microsoft doesn't list PDF as a data source in Excel for Mac |
| Google Sheets | Get the tables into Excel or CSV, then use File > Import in Sheets | Sheets can't import a PDF. Opening the PDF with Google Docs runs OCR, but it usually misses tables |
| Excel or Sheets, every day | An extraction tool exports just the fields and line items you need from each new PDF | You can download the extracted data from Docsumo to Excel. Its Data Table puts the data from every document of one type in one table, which you can export to CSV or Google Sheets |
For bank statements, see how to convert PDF bank statements to Excel.
Common PDF extraction failures and fixes#
| Problem | Fix |
|---|---|
| Poor, skewed or rotated scans: OCR misreads characters or reads lines out of order | Straighten and clean the page first; send low-confidence values to review |
| Broken text layer: old or badly made PDFs return scrambled characters | Use OCR wherever the text layer is clearly wrong |
| Multi-column pages: lines from the two columns get mixed together | Read each column as its own region |
| Complex tables: merged cells scramble columns, and rows break at page ends | Detect tables visually, drop repeated page headers and join the parts |
| Silent failures: a few files return wrong values nobody notices | Validate every result; route low-confidence values to a person |
How automated PDF data extraction works#
Automated PDF data extraction runs the same steps on every file, from the moment it arrives to the export. Nobody opens the PDF unless a value fails a check. It's one kind of automated data extraction. Automated document processing covers the wider process.
- Text-based PDFs
- Scanned PDFs
- Email attachments
- API uploads
- 01Classify and split
- 02OCR where there's no text
- 03Extract fields and tables
- 04Check and review
Set it up in this order.
- Pick one document typeStart with one, such as invoices or bank statements, and add others once it runs well.
- List the fieldsWrite down every field and table you need, and the format for each.
- Connect intakePDFs can come in by email, by upload or through an API. In Docsumo, one file can hold up to 500 pages.
- Split mixed filesWhen one PDF holds several documents, such as a loan packet, the software sorts them by type (classification). Then it cuts the file where each document starts (splitting). In Docsumo, auto-classification and splitting are on the Business plan.
- Set thresholds and checksChoose a confidence score. Any value scored below it goes to a person. Then choose the checks every file has to pass.
- ExportDownload to Excel, or send results to your ERP, database or loan system through an API and webhooks.
One utility bill, from inbox to spreadsheet#
Take the bill in the figure at the top of this page. Riverbend Electric & Gas emails Maple Court Apartments LLC its bill for August 5 to September 3, 2026. The PDF arrives in the team's shared inbox. Docsumo has its own email inbox, so if the email also goes there, nobody has to download the PDF and upload it again.
Page 1 holds the account, the charges and a summary for each meter, and page 2 lists the line items. Extraction returns the account number, 3108-5572-40, the billing period and one row per meter. Two meters are electric, at 9,420 kWh and 1,080 kWh, and one is gas, at 194 CCF.
Then the checks run. The three meter charges add up to $1,719.86 before tax. With $98.89 in taxes and fees, that's $1,818.75, the amount due on September 29. If any value had a low confidence score, a reviewer would see it, and clicking it highlights its source line on the page.
The values go to Excel, or to your AP system through the API and webhooks. The data from every bill like this one goes into the same Data Table. On the Enterprise plan, a check can also compare the first electric meter's supply rate of $0.0912 per kWh with the rate in your contract. See how Docsumo reads utility bills.
Checks to run on extracted PDF data#
Run these checks before the data reaches your systems.
- Totals add upLine items and tax sum to the total, and transactions reconcile to the closing balance.
- Required fields are presentEvery field your system needs is there, in the right format.
- Dates are validEach one is a real date, falls in a sensible range and comes in the right order.
- Names match your recordsVendor, customer or account details agree with your master data.
- It isn't a duplicateThe same document hasn't been processed before.
- Uncertain values were reviewedAnything below your confidence threshold went to a person first.
In Docsumo, fields below your confidence threshold go to a reviewer. Clicking a field highlights its source line on the page. You can add your own checks as workflow steps, either an AI step or your own Python code. Try it free for 14 days on up to 1,000 pages, and see pricing for the plans.
- 99%field-level accuracy across 250+ document types
- 95%+of documents processed straight through, without manual review
Which PDFs to automate first#
Count last month's PDFs by type. Start with the type that has the most files and the most layouts. Converters and templates fail on that type first. Run a batch of those files through the method you pick, and look at what a person still had to fix. When you're ready to compare tools, see PDF data extraction software.
Book a demo with a few of your own PDFs, or start a free trial.
Frequently asked questions#
How do I extract data from a PDF into Excel?
In Excel for Microsoft 365 on Windows, choose Data > Get Data > From File > From PDF, pick the tables you want and load them. For PDFs that arrive every day in many layouts, an extraction tool pulls out just the fields you need and exports them to Excel.
Can you extract data from a scanned PDF?
Yes, but it needs OCR (optical character recognition) first. A scanned PDF is only an image of the page, and OCR turns that image into text you can select, search and copy. After OCR, you still need rules or a model to find the specific fields.
How do I extract data from a PDF form?
If the form is fillable, read the field values directly. Adobe Acrobat can merge many filled forms into one spreadsheet, and Python's pypdf library returns the name and value of each field. A flattened form still has its text, so you need a step that pairs each label with its value. A scanned or handwritten form needs OCR first, then the same step.
What is a PDF scraper or parser?
A PDF scraper, or PDF parser, reads a PDF's text, tables and form fields and saves them as data, such as CSV or JSON. Basic scrapers return the text in page order. AI-based ones also work out what each value means, such as which number is the total due. Free tools handle tables in text-based PDFs, such as the pdfplumber and Camelot libraries and the Tabula app.
Can ChatGPT extract data from a PDF?
Yes. You can upload a PDF and ask ChatGPT for the values you need. OpenAI says that outside its Enterprise plan, ChatGPT reads the digital text in a PDF, not the images in it. Uploads are capped at 80 files every 3 hours, and at 3 a day on the free plan. For PDFs that arrive every day, you also need the same fields in the same format, checked totals and a review step.
How accurate is automated PDF data extraction?
It depends on document quality and variety, so test on your own files. Docsumo reaches 99% field-level accuracy across 250+ document types, and fields below your confidence threshold go to a person for review.
Sources
- Microsoft Support: Import data from data sources (Power Query), From PDF
- Microsoft Support: Power Query data sources in Excel versions
- Microsoft Learn: Pdf.Tables (MultiPageTables option)
- Google Docs Editors Help: Import data sets and spreadsheets
- Google Drive Help: Convert PDF and photo files to text
- Adobe Help: Convert PDFs to Excel and XML formats in Acrobat
- Adobe Help: Collect and manage PDF form data
- pypdf documentation: Interactions with PDF forms
- pdfplumber on GitHub
- PyPI: pdfplumber
- Camelot on GitHub
- Tabula on GitHub
- OpenAI Help Center: Uploading files and audio to ChatGPT
First published . Last updated .