Structured vs unstructured vs semi-structured data: differences and examples
For data, operations and IT teams: a clear comparison of the three data types, with examples, storage and analysis options, and what it takes to turn documents like invoices and bank statements into structured data.
Key takeaways
- Structured data follows a fixed schema of rows, columns and data types, such as a database table or a spreadsheet with defined columns.
- Semi-structured data carries its own labels, like keys or tags, but no fixed schema. JSON, XML, email headers and many business documents fall here.
- Unstructured data has no predefined model: free text, contracts, images, audio and video.
- Structured data goes in relational databases and is queried with SQL; semi-structured data suits document and NoSQL stores; unstructured data usually lives in file storage and data lakes.
- Business documents such as invoices and bank statements look semi-structured to a person but reach you as PDFs and scans, so they need OCR, classification, extraction and validation before they're usable.
On this page
- Structured vs semi-structured vs unstructured data at a glance
- What is structured data?
- What is semi-structured data?
- What is unstructured data?
- Unstructured data extraction: how documents become structured data
- What to look for in unstructured data extraction tools
- Using all three together
- The bottom line
- Frequently asked questions
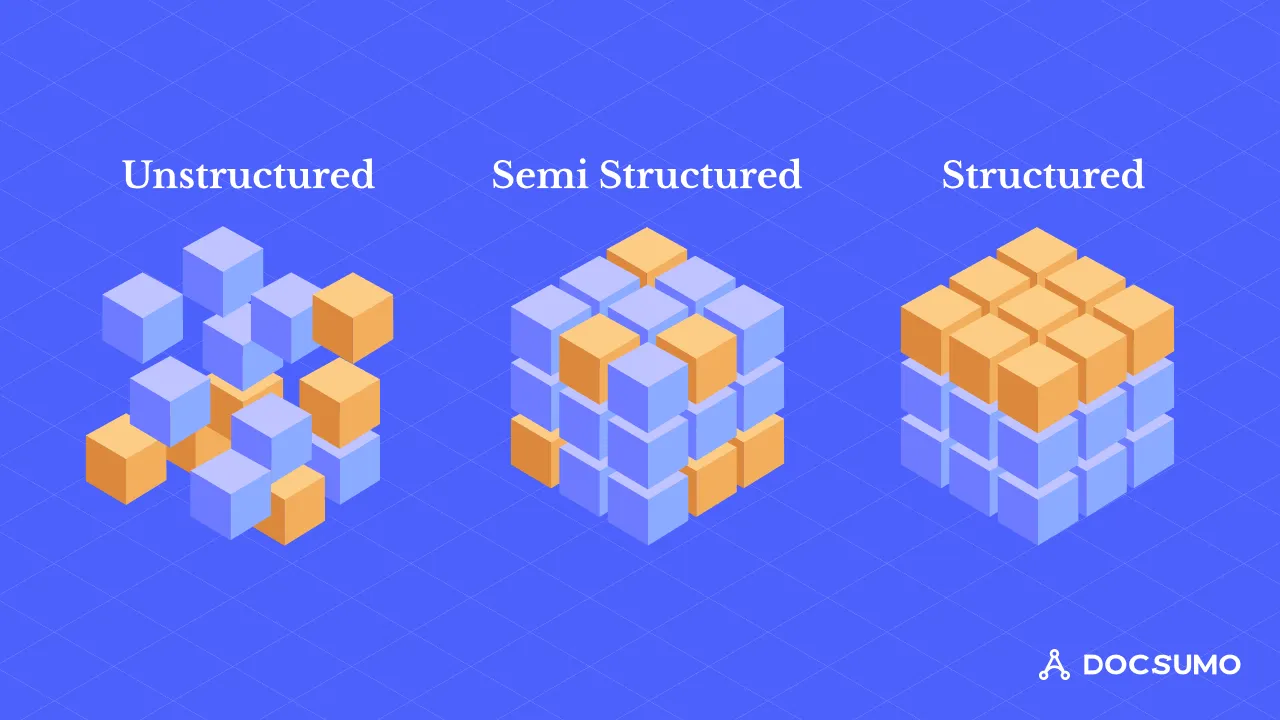
Structured, semi-structured and unstructured data differ in how much organization they carry. Structured data follows a fixed schema, such as a database table, so software can query it directly. Semi-structured data carries its own labels, like the keys in JSON, but no fixed schema, and unstructured data, such as free text, images and audio, has no predefined model and must be processed before it can be analyzed.
Structured vs semi-structured vs unstructured data at a glance#
Structured
A fixed schema of fields and types. Example: a loan table with loan ID, borrower, amount and funded date.Semi-structured
Labels travel with the values, but records can differ. Example: JSON from an API, or an email.Unstructured
No predefined model. Example: a contract, a call recording or a scanned page.
| Aspect | Structured | Semi-structured | Unstructured |
|---|---|---|---|
| Format | Fixed schema: defined fields and types | Self-describing labels (keys, tags), flexible schema | No predefined model |
| Examples | Database tables, spreadsheets, ledger entries | JSON, XML, email, logs, HTML, invoices and statements | Contracts, letters, notes, images, audio, video |
| Storage | Relational databases, data warehouses | Document and NoSQL databases, files, data lakes | File and object storage, data lakes |
| How it's queried | SQL | Query languages for JSON/XML, parsing | Search, NLP, computer vision, language models |
| Ease of analysis | Easiest | Moderate | Hardest |
| Schema changes | Need a migration | Easy to add fields | Not applicable |
What is structured data?#
Structured data fits a predefined model: every record has the same fields, and every field has a type. A loan table might have loan_id (integer), borrower_name (text), amount (decimal) and funded_date (date). Because the shape is known, you can sort, filter, join and total it with SQL in seconds.
Examples: customer records in a CRM, transactions in a core banking system, inventory in an ERP, a spreadsheet with consistent columns.
Advantages: fast queries, easy reporting and strong consistency. Limits: schema changes take planning, and much real-world information doesn't fit into columns.
What is semi-structured data?#
Semi-structured data has structure, but the structure travels with the data rather than living in a fixed schema. In JSON, each value has a key, but two records can have different keys:
{"invoice_no": "INV-20418", "vendor": "Harbor Street Supply", "total": 4812.30}
{"invoice_no": "INV-20419", "vendor": "Bayside Foods", "total": 912.00, "po_number": "PO-7731"}
Examples: JSON and XML, email (structured headers, free-text body), log files, HTML pages, API responses. Invoices, bank statements and pay stubs are usually called semi-structured too: every invoice has a vendor, number, date and total, but each vendor lays them out differently. More in our guide to semi-structured data.
Advantages: flexible and easy to exchange between systems. Limits: queries are more complex, and quality varies because no schema is enforced.
What is unstructured data?#
Unstructured data has no predefined model. The information is there, but software can't query it until something identifies what's in it. Most of the detail a business relies on lives here: the renewal clause in a lease, the cause of loss in a claim, the reason for a large deposit in a letter of explanation.
Text
Email bodies, letters, contracts, leases, policies, reports and notes.Scanned documents
Paper forms, signed agreements, faxes and phone photos of documents.Images
Product photos, damage photos for insurance claims, ID images.Audio and video
Call recordings, meetings, training videos.Web and social content
Pages, posts, reviews and comments.Messages
Chat logs, support tickets and text messages.
It's usually stored as files in object storage (such as Amazon S3 or Azure Blob Storage), data lakes and document management systems, with search indexes or vector databases on top. Storing it is easy; using it means extracting what's inside.
Unstructured data extraction: how documents become structured data#
Business documents such as bank statements, invoices, ACORD forms and tax forms hold semi-structured content, but they arrive as PDFs, scans, photos and email attachments, so as files they're unstructured. Unstructured data extraction turns them into rows:
- PDFs
- Scans and photos
- Email attachments
- 01OCR the pages
- 02Classify each document
- 03Extract fields and tables
- 04Validate the values
Validation is the step people skip: checking, for example, that a statement's opening balance plus its transactions equals the closing balance, and sending low-confidence values to a person. That's what intelligent document processing does. Docsumo, for example, takes documents by email, upload or API, reports 99% field-level accuracy on 250+ document types, and delivers the results through an API and webhooks.
What to look for in unstructured data extraction tools#
- No templates per layoutEvery sender formats things differently; models trained on many layouts cope, templates don't.
- OCR that handles real scansFaxes, phone photos, stamps and handwriting, not just clean PDFs.
- Tables, not just fieldsLine items and transactions, including tables that run across pages.
- Validation and reviewRules on totals and formats, confidence scores, and a person for uncertain values.
- A target schemaMap every source to one model before loading. See what is schema mapping.
- SecurityDocuments carry personal and financial data. Look for SOC 2 Type 2, HIPAA and GDPR coverage.
Using all three together#
Most analysis combines the three. A lender might join structured application and credit bureau fields in its loan origination system, semi-structured transactions extracted from bank statements as JSON, and the unstructured explanation letter or underwriter notes. Convert as much as possible into structured form early, keep a link back to the source document, and store each type where it's easiest to use.
The bottom line#
Structured data is ready to query, semi-structured data needs parsing, and unstructured data needs processing to find what's in it. Business documents sit in between: semi-structured content in unstructured files, and turning them into structured data is what makes the rest of your analysis possible. For more, read semi-structured data and data extraction from PDF.
Book a demo to see it on your own documents, or start a free trial.
Frequently asked questions#
What is the difference between structured and unstructured data?
Structured data is organized in a fixed format, such as rows and columns with defined data types, so it can be queried directly. Unstructured data has no predefined format, like the text of a contract or a scanned image, and needs processing before it can be analyzed.
What are examples of semi-structured data?
JSON and XML files, email (structured headers plus free-text body), log files, and HTML pages. Invoices, bank statements and forms are often called semi-structured because they contain the same kinds of fields in varying positions. See semi-structured data.
Which files count as unstructured data?
Video and image files, audio recordings, free-text documents, scanned pages and email bodies. A JSON or XML file is semi-structured, and a spreadsheet with consistent columns is structured.
Is a PDF structured or unstructured data?
A PDF is a container. A digital PDF invoice holds semi-structured content, while a scanned PDF is just an image. Either way, the data needs to be extracted before a system can use it. See data extraction from PDF.
What is unstructured data extraction?
Pulling specific facts, such as names, dates, amounts and table rows, out of documents, emails and images and saving them as structured fields a database or business system can use.
How do companies process and extract data from unstructured documents?
They run OCR to turn scans into text, classify each document, extract fields and tables with models or language models, validate the values against rules, and send uncertain values to a person. For business documents, intelligent document processing combines these steps.
Sources
First published . Last updated .