Automated data extraction: how it works and how to roll it out
For operations, finance and IT leaders replacing manual data entry: how automated extraction works, how templates and AI compare, where it pays off and how to roll it out.
Key takeaways
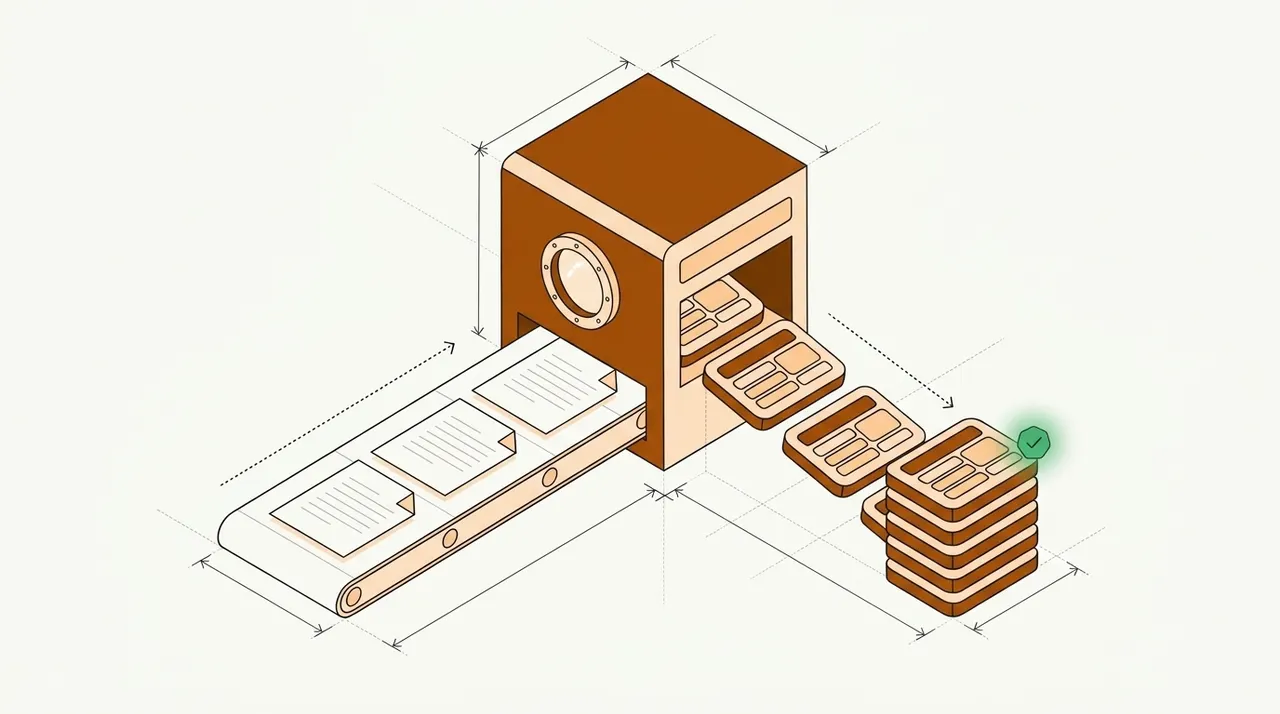
- Automated data extraction uses software, usually OCR plus AI models, to pull fields and tables out of documents and send them to business systems without people retyping them.
- It returns two kinds of output: key-value pairs (invoice number, account holder, policy dates) and tables (transactions, line items, rent roll units).
- Templates and rules work for a few fixed layouts; AI-based extraction reads layouts it hasn't seen and can be trained on your own documents.
- Good automation isn't touchless for everything: it validates each value and sends only low-confidence or failed fields to a person.
- Measure success by straight-through processing rate and total cost per document, not only extraction accuracy.
On this page
- What does automated data extraction extract?
- How automated data extraction works
- Rules, templates or AI: how the methods compare
- Why automate data extraction
- Where automated data extraction is used
- How to choose automated data extraction software
- How to roll out automated data extraction
- The bottom line
- Frequently asked questions
Automated data extraction is the use of software to pull specific data out of documents, such as invoices, bank statements, forms and contracts, and send it to business systems without anyone retyping it. Modern tools pair OCR, which turns pages into text, with AI models that find the right fields and tables, check them and flag anything uncertain for a person.
This guide covers what gets extracted, how it works, how the methods compare, where it's used and how to roll it out.
What does automated data extraction extract?#
Data comes off a document in two shapes. Key-value pairs are a label and its value, such as Statement period = Jul 1 to Jul 31, 2026; when the label isn't printed, the model infers it from layout. Tables hold the detail, such as transactions and line items, and are the hard part: they run across pages and change columns from sender to sender. More in table extraction from PDFs.
| Field | Extracted value | Confidence |
|---|---|---|
| Account holder | Harbor Street Bakery LLC | |
| Address | 118 Harbor St, Portland, ME | |
| Bank name | First Midwest Bank | |
| Account number | •••• 4821 | |
| Account type | Business checking | |
| Statement period | 2026-07-01 → 2026-07-31 |
| Field | Extracted value | Confidence |
|---|---|---|
| Opening balance | 42,180.55 | |
| Total deposits | 88,412.10 | |
| Total withdrawals | 91,686.44 | |
| Closing balance | 38,906.21 | |
| Transaction count | 142 |
| Field | Extracted value | Confidence |
|---|---|---|
| Date | 2026-07-14 | |
| Description | ACH DEPOSIT STRIPE PAYOUT | |
| Amount | +3,284.10 | |
| Debit / credit | Credit | |
| Running balance | 51,902.44 | |
| Category | Card processor payout |
How automated data extraction works#
- Upload
- API or cloud folder
- 01OCR
- 02Classify and split
- 03Extract
- 04Validate
- 05Review
OCR reads each page (digital PDFs mostly skip it), and mixed uploads are split by document type, so a loan packet becomes its statements, pay stubs and IDs. A model captures each field with a confidence score, rules check the values, and anything uncertain goes to a person before the data leaves through an API or webhook.
Rules, templates or AI: how the methods compare#
Manual extraction
- People type every value by hand
- Hours per file, more staff at every peak
- Typos surface downstream
- No record of where a value came from
Automated extraction
- Software fills in the fields
- Minutes per file, peaks without overtime
- Rules catch mistakes before the data is used
- Every value links to its place on the page
Automated tools differ in how they find the data. Templates and rules are precise on a few fixed layouts but break when a sender redesigns. AI-based extraction learns what a field looks like rather than where it sits, so it reads new layouts and scans; because it's probabilistic, it needs confidence scores and validation.
Why automate data extraction#
Docsumo's published figures:
- <5 minper document, down from 2+ hours by hand
- 99%field-level accuracy across 250+ document types
- 95%+of documents processed straight through, without manual review
- 95%straight-through processing on debt settlement documents at National Debt Relief
Automation also links every value to its source for audits, and runs cross-document checks a person may miss, such as pay stub income that doesn't match bank deposits.
Where automated data extraction is used#
Lending
Bank statements, pay stubs, tax returns and IDs for income verification and underwriting.Accounts payable
Invoices, purchase orders and receipts for matching, coding and payment.Insurance
ACORD forms, loss runs and certificates of insurance for submissions and COI compliance.Commercial real estate
Rent rolls, T-12s and offering memorandums for property underwriting.Logistics
Bills of lading, delivery notes and customs documents for tracking and freight billing.
More in IDP for lending and accounts payable automation.
How to choose automated data extraction software#
- Pre-trained modelsFor your main document types, and a way to train new ones.
- Accuracy on your documentsScore each field on a few hundred real files, bad scans included.
- TablesMulti-page tables come back whole.
- Validation and reviewRules, cross-document checks and a review screen that shows each value on its page.
- IntegrationsAn API and webhooks, plus exports such as Excel.
- SecuritySOC 2 Type 2, and HIPAA or GDPR where needed.
Compare total cost per document, not price per page: a cheaper tool that sends more to review can cost more. Docsumo's plans are on the pricing page.
Total cost per document
Per-page prices look small until you add the time people spend fixing what the tool gets wrong.
- Tool cost per month
- Review time per month
- Total per month
- Total cost per document
How it's worked out
- Tool cost = documents × pages × price per page.
- Review time = documents × the share reviewed × minutes per review ÷ 60 × hourly cost.
- Compare tools on the total per document, not the price per page: a cheaper tool that sends more documents to review can cost more.
How to roll out automated data extraction#
- Pick one workflowHigh volume and well understood, such as bank statements for underwriting.
- Baseline itDocuments per month, minutes each, error rate and backlog.
- Define fields and rulesEvery field you need and every check a reviewer runs now.
- Pilot on real documentsScore field-level accuracy and straight-through rate.
- Set confidence thresholdsDecide which values go straight through and which go to review.
- IntegrateSend the output to the system that uses it.
- ExpandAdd document types once the first workflow is stable.
The bottom line#
Automated data extraction replaces typing with checking: OCR reads the page, AI models find the fields, rules validate them and people review only what fails. Start with one high-volume workflow and measure straight-through rate and cost per document. For the basics, read what is data extraction.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions#
Can data extraction be automated?
Yes. OCR converts documents to text, and AI models identify the fields and tables you need. With validation rules and a review step for uncertain values, most documents can pass through without anyone typing.
What is the best way to automate data extraction from PDFs?
For a few fixed layouts, a template or rule-based parser works. For many layouts, scans or high volume, use an intelligent document processing platform with pre-trained models for your document types. See our guide to extracting data from PDFs.
How accurate is automated data extraction?
It depends on the tool and your documents. Docsumo reports 99% field-level accuracy on 250+ document types. Always test a tool on a sample of your own documents, including poor scans.
How long does it take to set up automated data extraction?
With pre-trained models for common documents like bank statements, invoices or ACORD forms, a pilot can start on the first day of a free trial. Custom document types need sample documents to train a model, and integration work depends on your systems.
Is automated data extraction the same as web scraping?
No. Web scraping, or automated web data extraction, pulls data from the code of web pages. Document data extraction reads files such as PDFs, scans and photos, where OCR and AI models have to find the data on the page. This guide covers documents; see data extraction vs data scraping for the difference.
What is the difference between automated data extraction and RPA?
RPA mimics clicks and keystrokes to move data between applications. Automated data extraction reads the documents themselves. They're often used together, with extraction feeding structured data to a bot or workflow.