Textract vs Azure Document Intelligence vs Google Document AI: what each one sorts, reads and leaves for you to build
For AI, engineering and operations teams choosing a cloud document API. See what each service sorts and reads, what you label first, and what you still build yourself.
Key takeaways
- Amazon Textract has no classifier you can train on your own document types. Its Analyze Lending API sorts mortgage packages only. To sort other documents, AWS teams use Amazon Comprehend or Bedrock Data Automation.
- Azure Document Intelligence trains a classifier from at least two document types and five labeled samples of each. It splits a combined file only when you set its split mode to auto.
- Google's Document AI custom classifier can sort English documents from type names and descriptions alone, with no training. It costs $5 per 1,000 pages for the first million pages a month.
- All three give each result a confidence score, but none offers new customers a review queue. Your team builds and staffs the review step.
- Compare total cost per document, not the price per page. The page price leaves out the time people spend checking and fixing results.
On this page
- The three services at a glance
- Classification: what each one sorts, and what it needs from you
- Splitting a combined file
- Extraction: ready-made models and custom fields
- What each vendor does with your documents
- Human review is the part you build
- What the per-page price leaves out
- When a cloud API fits, and when a platform fits
- Put one week of real files through each
- Frequently asked questions
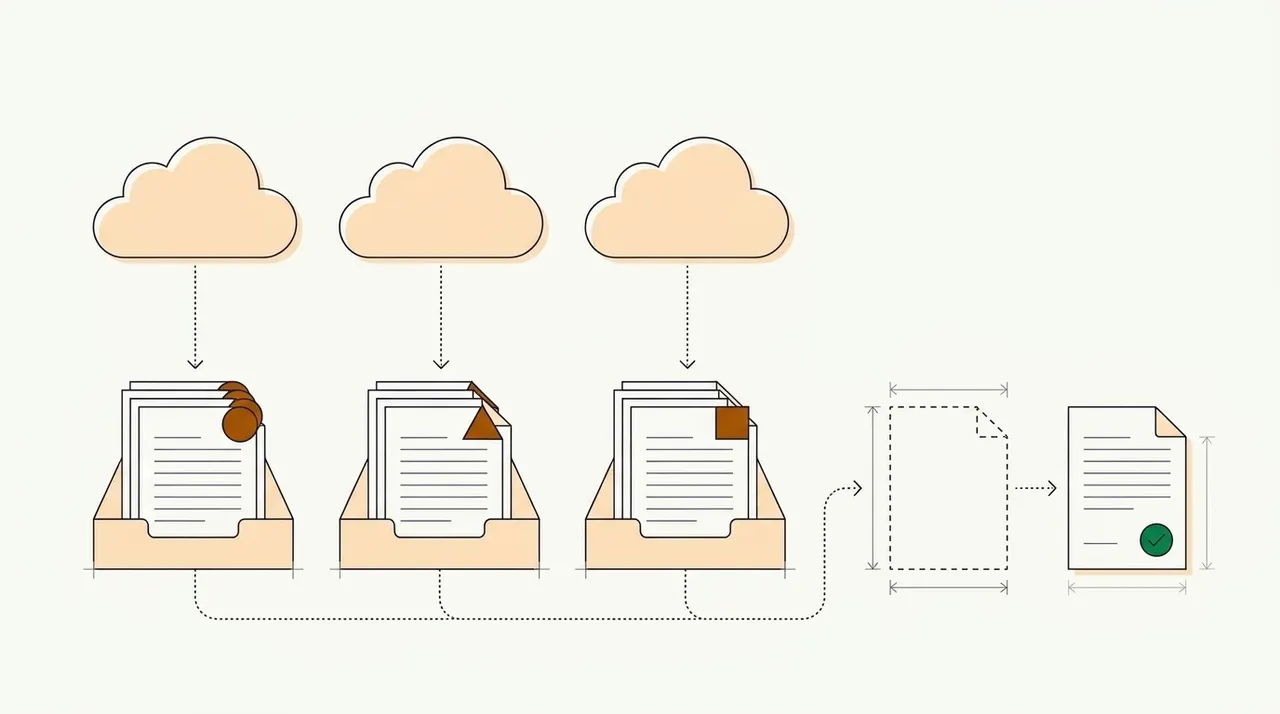
Textract, Azure Document Intelligence and Google Document AI are cloud tools that read a file and send back what it says. Azure and Google each sell a custom classifier that labels each document by type. Textract sorts only mortgage packages. To sort the rest, AWS teams can add Amazon Comprehend or Bedrock Data Automation. All three give each result a confidence score, a number for how sure the service is. None offers new customers a review queue, where people check the uncertain results.
We compared the three services using each vendor's own documentation and pricing pages, checked on October 8, 2026. We didn't run an accuracy test of our own. Docsumo, our product, is a document processing platform that your team works in, and it has its own API. We say where it fits near the end.
Which team are you?
The three services at a glance#
Each of the three is a set of APIs that your engineers call from their own code. Docsumo is a platform your team works in, and it has an API too. Here is what each one does with a file that holds several documents.
| Tool | Sorts documents | Splits files | Review queue | Classifier price |
|---|---|---|---|---|
| Document processing platform1 tool | ||||
| DocsumoOur product | Types you name, with no training set | Yes, with AI Split | Yes | Free trial; quoted plans |
| Cloud API3 tools | ||||
| Amazon Textract | Mortgage packages only | Mortgage packages only | No | $0.07 a page (Analyze Lending, includes extraction) |
| Azure Document Intelligence | Trained from 5 samples per type | Yes, when split mode is auto | No | $3 per 1,000 pages |
| Google Document AI | From type names, or trained | Yes, with a separate splitter | No | $5 per 1,000 pages |
These are list prices for the lowest volume. AWS's price is for its US West (Oregon) region, and Microsoft's is for East US. Google's price covers the first million pages a month. Textract's price includes extraction, so it isn't directly comparable with the two classifier prices.
Classification: what each one sorts, and what it needs from you#
Classification decides what each document is, such as an application, a loss run or a bank statement. The three services differ most in how you teach them your own document types. On AWS, classification lives in three different services.
| Service | How you define types | Minimum to start | Documents that fit no type | Price |
|---|---|---|---|---|
| Textract Analyze Lending | AWS's fixed list of mortgage document types | Nothing to train | Labeled UNCLASSIFIED | $0.07 a page (includes extraction) |
| Amazon Comprehend | Labeled training files | 50 documents per type | AWS's docs don't say | $3 an hour to train, plus a charge for each use |
| Bedrock Data Automation | A blueprint for each type, described in words | AWS's docs describe no training step | No match, or a fallback blueprint you set | $0.04 a page (custom output, includes extraction) |
| Azure custom classifier | Labeled samples | 2 types, 5 samples of each | A confidence threshold or an "other" type | $3 per 1,000 pages |
| Google custom classifier | Type names and descriptions, or training | None; 10 per type if you train it | A catch-all type | $5 per 1,000 pages |
Microsoft also sells Azure Content Understanding, which sorts files into up to 200 categories you describe, with no training. Microsoft says to add a category called "other". Without it, every file goes into one of the categories you described, even when none fits. Google's processor list shows that its classifier works in English only. For a longer list that includes document processing platforms, see our comparison of document classification software.
One insurance submission, set up three ways
Take a commercial property submission that a broker emails as one PDF. It holds five document types. They are the ACORD 125 application, the ACORD 140 property section, a statement of values, loss runs and the expiring policy's declarations page.
On Azure, you label at least five samples of each type, 25 documents in all, and train the classifier. Microsoft says training in Document Intelligence Studio takes a few minutes. Splitting stays off until you set the split mode to auto.
On Google, you can start with five type names and a sentence describing each one. If the results aren't good enough, you can train the classifier. Google's own example for five types uses 50 documents to train it and 50 to test it, 100 in all. Training can take several hours.
On AWS, Textract's lending list has no insurance forms in it. Comprehend needs at least 50 labeled documents per type, 250 in all. Bedrock Data Automation needs a blueprint for each of the five types instead, written as a description and a list of fields.
Our take. A training minimum tells you when a classifier can start, not how well it will sort your files. We'd judge each service by what your reviewers had to fix on a few hundred of your own submissions. Count the pages filed under the wrong type, and the splits made at the wrong page. That count matters more than any vendor's sample results.
Splitting a combined file#
Many files hold several documents in one PDF, like the submission above. The service has to find where each document starts and ends before it can sort them.
| Service | How it splits | On by default |
|---|---|---|
| Textract Analyze Lending | Splits a mortgage package into pages and groups them by document type | Yes |
| Bedrock Data Automation | Splits at each document's boundaries, up to 3,000 pages a file and 20 pages a document | No, you turn it on |
| Azure custom classifier | Finds each document and its page range when split mode is auto | No, the default is none |
| Google custom splitter | A separate processor that returns page ranges and a type for each document. It works from type names, or after training | Yes, that is what it does |
Google's splitter predicts the page ranges but doesn't cut the file. Google's software development kit (SDK) has code that cuts the file at those page ranges. Google suggests that a person checks the page ranges before the file is cut. Docsumo's AI Split takes a plain-English definition of each document type.
Extraction: ready-made models and custom fields#
After sorting comes reading. On all three, reading plain text costs $1.50 per 1,000 pages at the lowest paid volume. The services differ in their ready-made models and in how you teach them new fields.
| Service | Ready-made models | Custom fields | Custom price |
|---|---|---|---|
| Amazon Textract | Invoices and receipts, IDs, mortgage packages | Custom Queries, trained on at least 5 training and 5 test documents | $0.025 a page |
| Azure Document Intelligence | Invoices, receipts, IDs, bank statements, checks, pay stubs, contracts, US tax and mortgage forms | Template or neural models, from 5 labeled samples | $30 per 1,000 pages |
| Google Document AI | Invoices, expenses, bank statements, pay slips, W-2s, US driver's licenses | Custom extractor, from a field list alone or after training | $30 per 1,000 pages |
Language support differs too. Textract reads printed text in six languages and handwriting in English only. Azure lists hundreds of printed languages and 12 for handwriting. Google's text reader covers more than 200 languages, but its classifier, splitter and generative extractor list English only.
What each vendor does with your documents#
The three vendors treat your documents differently. Unless you opt out through an AWS Organizations policy, AWS may store Textract inputs and use them to improve Textract and other Amazon AI. Google says it never uses customer data to train its Document AI models. Microsoft deletes Document Intelligence inputs and results 24 hours after each analysis.
Docsumo doesn't use your documents to train shared or third-party models.
Human review is the part you build#
Each service gives its results a confidence score, which says how sure it is. What happens to a low score is up to you. AWS suggests writing your own rule, such as flagging anything under 95%. Microsoft's example sends results scored below 0.80 to a person.
None of the vendors offers a review tool to new customers. Amazon Augmented AI (A2I) sends Textract results to human reviewers, but it no longer takes new customers. Google deprecated, or began to withdraw, Document AI's Human-in-the-Loop review feature on January 16, 2024, and names no replacement. Microsoft's Document Intelligence docs describe confidence scores and thresholds, but no review queue.
So your engineers build the review step. Reviewers need a queue of uncertain results and a screen that shows each value next to its place on the page. They need a way to correct a value and send the document on. You also need a record of who changed what, and people to work the queue every day.
Docsumo includes the review queue and the review screen, and your own staff do the reviewing. Fields below the confidence threshold you set for each field go to your reviewers. Clicking a field highlights its source line in the document, and reviewer corrections improve the model. Audit logging, a record of who changed what, is on the Business plan.
What the per-page price leaves out#
The three services publish low per-page prices. Classification adds $3 per 1,000 pages on Azure and $5 on Google. AWS's Analyze Lending costs $70 per 1,000 pages, and Bedrock Data Automation's custom output costs $40, but both of those prices include extraction.
Some costs sit outside the page price. Google charges $0.05 an hour to host a custom processor version, which comes to $438 a year. A real-time Comprehend endpoint is billed for as long as it runs, even when no documents arrive. Review time can cost more than the API itself. Put your own numbers in the calculator below. It asks for a price per page, so $3 per 1,000 pages is $0.003 a page.
Cost per document: the API price plus review time
Per-page prices look small until you add the time people spend fixing what the tool gets wrong.
- Tool cost per month
- Review time per month
- Total per month
- Total cost per document
How it's worked out
- Tool cost = documents × pages × price per page.
- Review time = documents × the share reviewed × minutes per review ÷ 60 × hourly cost.
- Compare tools on the total per document, not the price per page: a cheaper tool that sends more documents to review can cost more.
In the calculator, use the share of documents your reviewers had to check or fix in a pilot, a trial run on your own files. Don't use a vendor's estimate. A cheaper service that sends more documents to review can cost more per document.
When a cloud API fits, and when a platform fits#
The choice comes down to who will run the process every day.
Build on a cloud API
- Engineers write the code that sorts and reads each file.
- Engineers build and maintain the review screen.
- Checks between documents live in your own code.
- Prices are published per page.
Run a document platform
- Your team sets up document types and checks in the product.
- Uncertain results wait in a built-in review queue.
- Checks between documents are rules you set up.
- Plans are often quoted rather than published.
A cloud API fits when your engineers want to control every step. It also fits when documents must stay with the cloud provider you already use. Azure's Read and Layout models can even run on your own servers, in software containers. A document intelligence platform fits when the team that processes the documents should run the process. Our guide to document intelligence covers the API-or-platform choice in more depth.
Docsumo is built for that second case. It sorts files into the document types you name, with no training set, and a new type works from the first document. Every label has a confidence score, and documents it can't classify wait as Unclassified for a person to assign. Auto-classification and splitting are on the Business plan. Checks between documents are on the Enterprise plan. Data goes to your systems through the API and webhooks. Docsumo is cloud-hosted only, so it can't run inside your own cloud account or on your own servers.
We compare Docsumo with each service on its own page, for Amazon Textract, Azure Document Intelligence and Google Document AI. Software companies that add document reading to their own product can start with the document extraction API. Insurance teams can see how submissions are sorted and checked on the insurance page.
Put one week of real files through each#
Take a week of real files, including the hardest scans, and run them through each option you shortlist. Engineers who work in AWS, Azure or Google Cloud can start with their own cloud's API and budget for the review step. If you'd rather not build that step, run the same files through Docsumo.
Book a demo and bring a week of real submissions, or start a free trial.
Frequently asked questions#
Does Amazon Textract classify documents?
Only mortgage documents. Textract's Analyze Lending API splits a loan package into pages and labels each page from AWS's list of mortgage document types. For other documents, AWS offers two other services. Amazon Comprehend trains a classifier on labeled files, and Bedrock Data Automation matches documents to blueprints you describe.
How many training documents does a custom classifier need?
Azure's custom classifier needs at least two document types and five labeled samples of each. Google's classifier can start with none. If you train it, Google recommends at least 10 documents per type in both the training set and the test set. Amazon Comprehend needs at least 50 training documents per type when each document gets one label.
Which is cheaper, Azure Document Intelligence or Google Document AI?
For classification, Azure lists $3 per 1,000 pages and Google lists $5 per 1,000 pages for the first million pages a month. For reading plain text, both list $1.50 per 1,000 pages. Then add the cost of your team's review time.
Do Textract, Azure and Google Document AI include human review?
Not for new customers. AWS's review service, Amazon Augmented AI (A2I), is closed to new customers, and Google deprecated Document AI's Human-in-the-Loop feature in January 2024. Azure returns confidence scores and leaves the review step to you.
Is Azure Form Recognizer the same as Azure Document Intelligence?
Yes. Form Recognizer is the service's former name. Microsoft now calls it Azure Document Intelligence in Foundry Tools and describes it as part of Azure Content Understanding.
Sources
- AWS: Amazon Textract pricing
- AWS: Amazon Textract FAQs
- AWS: Analyzing lending documents with Amazon Textract
- AWS: Analyze Lending response objects and document types
- AWS: Customizing Queries responses with Textract adapters
- AWS: Amazon Comprehend custom classification
- AWS: Amazon Comprehend guidelines and quotas
- AWS: Amazon Comprehend pricing
- AWS: Bedrock Data Automation document splitting
- AWS: Bedrock Data Automation blueprints
- AWS: Bedrock Data Automation fallback blueprints
- AWS: Amazon Bedrock Data Automation
- AWS: Amazon Bedrock pricing
- AWS: Amazon Augmented AI (A2I) human review, SageMaker developer guide
- AWS: Services in maintenance
- Microsoft: Document Intelligence custom classification model (v4.0)
- Microsoft: Document Intelligence custom models (v4.0)
- Microsoft: What is Azure Document Intelligence in Foundry Tools?
- Microsoft: Document Intelligence accuracy and confidence scores
- Microsoft: Transparency note for Document Intelligence
- Microsoft: Document Intelligence language support (OCR)
- Microsoft: Install and run Document Intelligence containers
- Microsoft: Content Understanding classifier
- Microsoft: Azure Document Intelligence pricing
- Microsoft: Azure Document Intelligence in Foundry Tools (product page)
- Google Cloud: Document AI custom classifier
- Google Cloud: Document AI custom splitter
- Google Cloud: Document AI processor list
- Google Cloud: Document AI custom extractor
- Google Cloud: Document AI quotas and limits
- Google Cloud: Document AI deprecations
- Google Cloud: Document AI release notes
- Google Cloud: Document AI pricing
- Microsoft: Build and train a custom classifier (v4.0)
- Microsoft: Document Intelligence FAQ (formerly Form Recognizer)
- Microsoft: Data, privacy and security for Document Intelligence
- Google Cloud: Document AI custom extractor with generative AI
- Google Cloud: Document AI security
- Google Cloud: Document AI product page
First published .