Loss run data extraction: turning any carrier's loss runs into data
For underwriting operations and the AI and automation teams building submission intake. The fields to pull from a loss run, where extraction breaks, and how to test a tool on your own files.
Key takeaways
- Loss run data extraction turns each carrier's loss run into one structured record, with the policy and its period at the top and one row per claim below.
- The claim rows carry the fields underwriters use: date of loss, status, and the amounts paid, reserved and incurred, read as of the report's valuation date.
- Loss runs are hard to extract because every carrier formats them differently, and one report can mix several policies, page-spanning tables and subtotal rows.
- A clean read isn't the finish line. Checks against the submission, such as the years covered and the losses on the application, catch what extraction alone can't.
- Test any OCR or extraction tool on your own loss runs, scored by the fields a person had to fix.
On this page
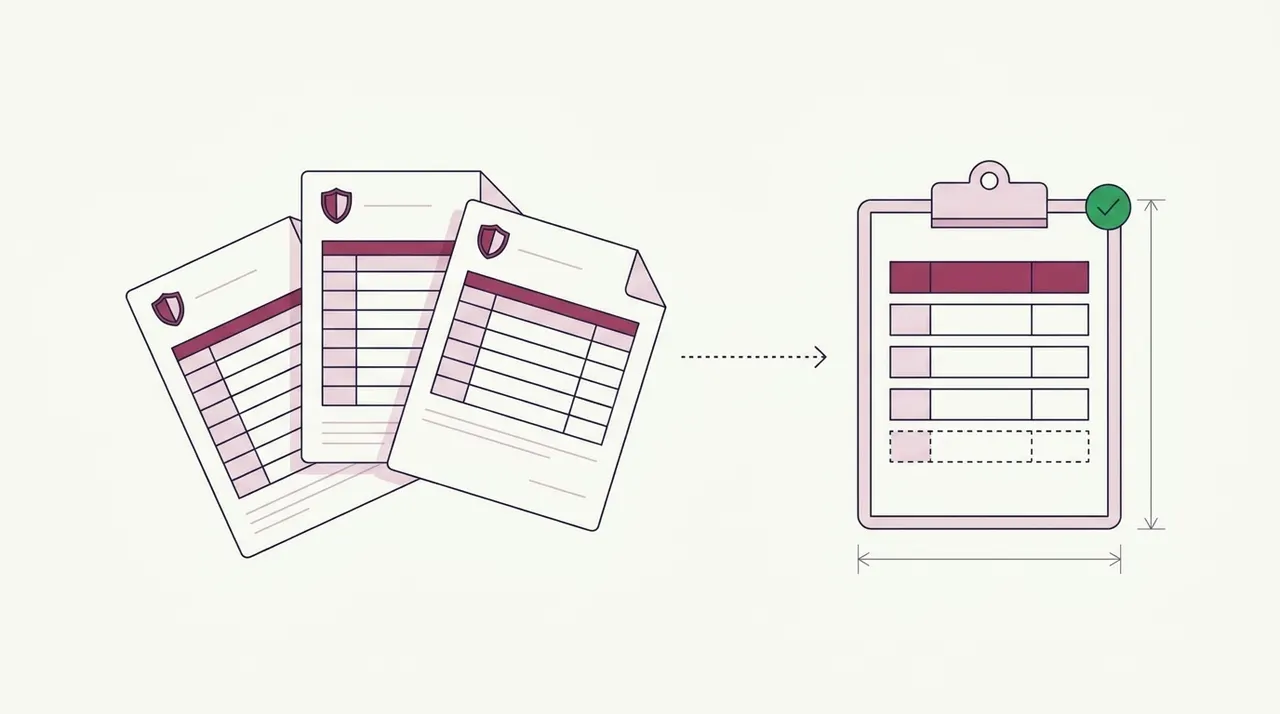
Loss run data extraction turns the loss runs in a submission, each in its carrier's own layout, into one structured record per report, with the policy and its period at the top and a row for every claim. Carriers, MGAs and brokers automate it so an account's claims history reaches the underwriter as data that can be checked, instead of PDFs someone retypes.
For AI and automation teams, loss runs are also a fair test of any OCR or extraction tool, because one document holds most of the hard cases.
What to extract from a loss run#
A loss run has two levels, and extraction should keep them apart. Report and policy fields describe the whole document. Claim fields repeat for every claim, and each claim has to stay attached to the right policy when one report covers several.
| Level | Fields | Watch for |
|---|---|---|
| Report and policy | Carrier, named insured, policy number, line of coverage, policy period, valuation date | Several policies in one report; a valuation date printed only in the header |
| Claim | Claim number, date of loss, date reported, claimant or description, cause, status | Status wording that differs by carrier |
| Amounts | Paid, reserve, recoveries, incurred, split by type where the carrier splits them | Whether incurred is before or after recoveries |
| Totals | Claim count and incurred per policy year and for the report | Subtotal rows that look like claims |
Some state laws set a floor. In Florida, a loss run statement must show the policy number, the period of coverage, the number of claims, the paid losses and the date of each loss. New York's rule asks for open and closed claims and notices of occurrence, each with its date and description. Everything past that floor varies by carrier, which is why the schema should be yours rather than any one carrier's.
Why loss runs are a hard extraction problem#
A clean one-page form is the easy case. Loss runs go wrong in other ways.
No standard layout
Each carrier prints its own report, and a carrier can change its format between years. A template per carrier can break the first time one does.Tables across pages
A long account history runs over many pages, sometimes with the column headers only on the first. The rows on later pages still need their columns.Rows that aren't claims
Subtotals, policy headers and "no claims" lines can sit inside the claim table. Counting them as claims inflates the history.Scans and faxes
Some loss runs arrive as scanned or faxed copies, and the quality of the read decides everything downstream.Summaries and letters
Some reports put totals per policy year on a summary page apart from the claim detail, and an account with no losses may send a no-known-loss letter instead. Both need recording as what they are.
Paid, reserved and incurred#
Normalizing amounts across carriers starts with three definitions. Paid is what the carrier has already paid out on a claim. The reserve is its estimate of what the claim will still cost, and on an open claim it can move with every new report.
Incurred is the two added together. IRMI's glossary defines incurred losses as the total of paid claims and loss reserves for a period, usually a policy year. Carriers label these columns differently. Decide up front whether your incurred field is gross or net of recoveries such as subrogation, and map every carrier to that one choice.
The valuation date is the cutoff for all of those numbers, the date after which the report reflects no further changes to paid amounts or reserves. Store it with every report. Two loss runs valued months apart can disagree on the same claim and both be right.
One loss run, extracted and checked#
Here is the loss run from the submission on our insurance page, rolled up by policy year. Cedar Ridge Storage LLC is a commercial property and general liability account with a proposed effective date of November 1, 2026. Its prior carrier's report is valued September 15, 2026.
| Policy year | Claims | Status | Paid | Reserve | Incurred |
|---|---|---|---|---|---|
| 2025–26 | 1 | Closed | $7,150.00 | $0.00 | $7,150.00 |
| 2024–25 | 1 | Closed | $31,250.00 | $0.00 | $31,250.00 |
| 2023–24 | 0 | None | $0.00 | $0.00 | $0.00 |
| 2022–23 | 0 | None | $0.00 | $0.00 | $0.00 |
| Total | 2 | 0 open | $38,400.00 | $0.00 | $38,400.00 |
Cedar Ridge Storage LLC, prior carrier, valued 2026-09-15. Both claims are closed, so paid and incurred match.
Getting the numbers out is half the work. Whether the file is ready for an underwriter depends on checks like these, run as soon as the data is extracted.
- ArithmeticPaid plus reserve matches incurred on each claim, allowing for recoveries if your incurred is net, and the claims add up to each year's total.
- Years coveredThe runs cover every policy year your guideline asks for, with no gap where the account changed carriers.
- Valuation dateRecent enough for your rules, counted back from the proposed effective date.
- Losses on the applicationEvery loss the applicant reported is on a loss run, and every claim on the runs was reported.
- Every prior carrierEach carrier on the application has a loss run, or a report showing no losses.
- Named insured and policy numbersThey match the applicant and the prior policies on the application.
Guidelines differ on the years. Insurers usually ask for three to five years of claims history, and one construction program's submission rules want five years valued within 90 days of the effective date. Against a five-year guideline, the Cedar Ridge file mostly passes. The ACORD 125 reports 2 losses in the last 5 years and the loss runs show the same 2 claims, and the report was valued 47 days before the effective date. The miss is the years. The file holds four policy years, 2022 to 2026, so your team asks the broker for the 2021–22 year before an underwriter spends time on the account.
How to automate loss run processing#
- Broker email
- Uploads
- Scanned copies
- 01Split the submission
- 02Extract each loss run
- 03Join tables across pages
- 04Check against the application
Docsumo is an intelligent document processing platform, and loss runs are among the insurance documents it reads. Submissions come in by email, upload or API. On the Business plan it classifies a mixed packet and splits it, so the loss runs separate from the ACORD forms and schedules. It isn't limited to pre-built models, it joins tables that run across pages into one table with the headers mapped, and it reads handwritten as well as printed text.
On the Enterprise plan, cross-document validation checks the loss runs against the losses on the application. Checks against your own guidelines, such as years covered or valuation date, are steps you set up in the workflow, and a step can call an LLM or run your own Python. Confidence thresholds are set per field. Fields below them go to a person for review, clicking a field highlights its source line in the document, and reviewer corrections improve the model. The data leaves through the API and webhooks or as an Excel export.
For technical buyers, the rest of the checklist is on the security page. Docsumo is cloud only, SOC 2 Type 2 audited and ISO/IEC 27001:2022 certified, encrypts data in transit and at rest, supports SSO, and doesn't use customer documents to train shared or third-party models. It supplies the software, not a managed review team, so your own staff clear the exceptions.
How to test a loss run extraction tool#
A vendor's sample file proves little. A test on your own files shows how a tool handles what you actually receive.
- Build a pilot set from your own submissionsTake loss runs from as many carriers as you receive, including the longest reports and the scans, and key the correct values by hand.
- Fix the schema before you scoreDecide the policy and claim fields, the status values and whether incurred is net of recoveries, so every tool aims at the same target.
- Score field by fieldCount the fields a person had to fix, per field. A wrong incurred amount costs more than a misspelled claimant name.
- Look at what gets flaggedLow-confidence fields and failed checks should reach a reviewer with the reason and the source line, rather than slip through.
- Check the outputThe claim table should arrive in your schema through the API or a webhook, ready for your rating or policy system.
Our take. Judge a loss run tool by the corrections your own team had to make, not by a vendor's headline accuracy number. A figure measured on someone else's documents says little about how a regional carrier's long scanned report will come out, and that report is the one your underwriters wait on.
When loss runs hold up the quote#
If submissions sit in a queue while someone retypes loss runs, extraction and the checks above are the part to automate first. The underwriting judgment stays with the underwriter. The same approach covers the rest of the submission, from the ACORD forms to the schedules, and insurance data extraction walks through it.
Book a demo with a few of your own loss runs, or start a free trial.
Frequently asked questions#
What is loss run data extraction?
It's pulling the policy and claim data out of loss run reports, whatever the carrier's layout, into structured fields such as claim number, date of loss, status, paid, reserve and incurred. Underwriting teams use the result to review an account's claims history and check it against the application.
Can AI extract data from loss runs?
Yes. OCR reads the characters, and AI models turn them into fields and tables, including tables that run across pages. Fields the model isn't confident about should go to a person with the source line in view, not straight into your system.
What fields should you extract from a loss run?
At the policy level, the carrier, named insured, policy number, policy period and valuation date. For each claim, the claim number, date of loss, date reported, description or cause, status, and the amounts paid, reserved and incurred, plus any recoveries.
How do you handle loss runs from different carriers?
Map every carrier's columns onto one schema of your own instead of keeping a template per carrier. Settle the definitions first, such as whether incurred is before or after recoveries, and check each claim's paid plus reserve against its incurred figure.
Is OCR enough to process loss runs?
No. OCR returns text, not a claims table. You still need extraction that keeps each claim with its policy, joins tables across pages and leaves subtotal rows out of the claim count, followed by checks and a review step for low-confidence fields. See OCR in insurance.
Sources
- The 2026 Florida Statutes, 626.9202: Loss run statements for all lines of insurance
- New York Insurance Law, Section 3426
- IRMI glossary: Incurred losses
- IRMI glossary: Valuation date
- Insureon: Loss runs (insurance glossary)
- Construction Insurance Services: Underwriting submission requirements
First published .