Zonal OCR: how template-based OCR works and when it breaks
For operations and IT teams automating forms and invoices: how zonal (template) OCR works, a simple example, where it still makes sense, and why teams with varied layouts move to AI-based extraction.
Key takeaways
- Zonal OCR (also called template OCR) reads text only from predefined areas, or zones, of a page, and maps each zone to a named field such as invoice number or total.
- It works well when every document shares the same layout, such as an internal form, a single vendor's invoice or a standardized government form.
- It breaks when layouts vary or shift: a new vendor, a redesigned form, a skewed scan or a table that runs longer than the zone all cause misses.
- Anchors, regular expressions and smart zones make templates more tolerant, but every new layout still needs a new template.
- AI-based extraction finds fields by content and context instead of fixed position, so one model covers many layouts.
On this page
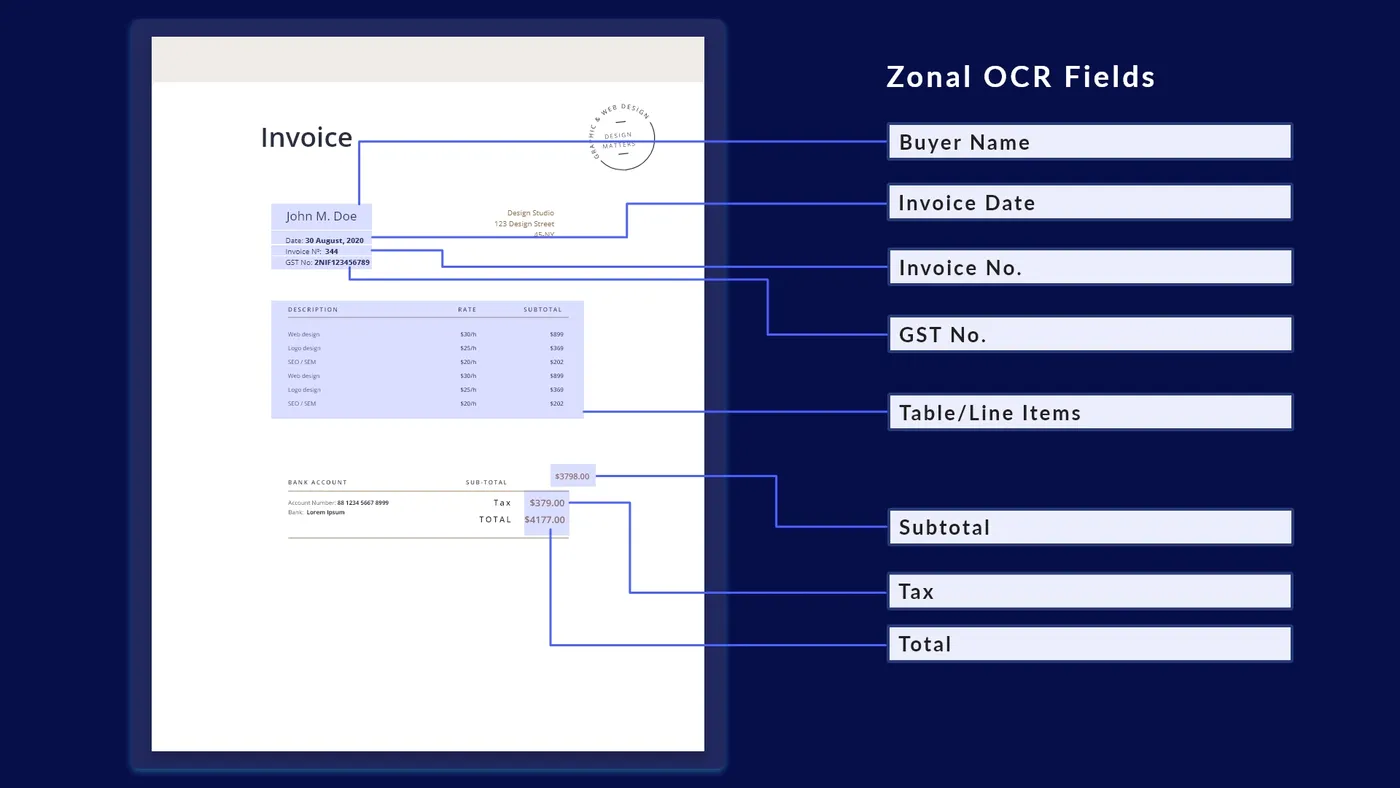
Zonal OCR is optical character recognition that reads text only from predefined areas, or zones, of a document. You build a template by drawing a box around each field, such as the invoice number, date or total, and the software reads each box and labels the result with the field name. It's fast and precise when every document shares the same layout, and it breaks when layouts vary.
This guide explains how zonal OCR works, shows a simple example, covers where it fits and where it fails, and describes the AI-based alternatives.
What is zonal OCR?#
Standard OCR reads every piece of text on a page and returns it in reading order. Zonal OCR, also called template OCR, adds a map: a template that says "the invoice number is in this rectangle, the date is in that one." The output is structured, a set of field names and values, instead of a block of text.
It's one of the oldest ways to get structured data out of documents, and it's still built into many scanning and capture tools.
How zonal OCR works#
- Scanned forms
- Invoices from one sender
- Fixed-layout PDFs
- 01Match the page to the template
- 02OCR each zone
- 03Check each value's format
- Create a templateUsing a sample document, draw a zone around each field and give it a name.
- Align incoming pagesScanned pages are deskewed and matched to the template, often using registration marks or anchor text.
- OCR each zoneThe engine reads only the text inside each zone, often with settings tuned for the field (digits only, a single line).
- ValidateRegular expressions or rules check each value's format, such as a date pattern or an invoice number prefix.
- ExportValues go to a spreadsheet, database or business system.
A simple example in Python
Here's the core idea with pytesseract: crop a fixed region and read it as a single line.
from PIL import Image
import pytesseract

page = Image.open("invoice.png")

# zones as (left, top, right, bottom) pixel boxes, measured on the template
zones = {
    "invoice_number": (1150, 190, 1500, 225),
    "invoice_date":   (1150, 230, 1500, 265),
    "total":          (1150, 1480, 1500, 1520),
}

fields = {
    name: pytesseract.image_to_string(page.crop(box), config="--psm 7").strip()
    for name, box in zones.items()
}
print(fields)
--psm 7 tells Tesseract to treat each crop as a single line of text. The weakness is obvious: if the next invoice puts its total 40 pixels lower, the zone reads the wrong thing or nothing.
Smart zones and anchors
To make templates more tolerant, capture tools add three techniques:
Anchors
Find a label such as "Invoice No." and read the value relative to it, instead of at fixed coordinates.Regular expressions
Search a larger zone for a pattern, such asINV-\d+.Dynamic zones
Grow a zone down the page to capture a table until a stop word like "Subtotal".
These help, but each layout still needs its own template and rules.
Where zonal OCR works well#
Zonal OCR is a sound choice when your documents match one of these:
- Internal formsYou design and control the layout.
- Standardized formsA fixed layout, such as a government or industry form, when you receive only the official version.
- A single sender's documentsOne supplier's invoices or one bank's statements.
- High-volume, low-variety batchesOne template covers most pages.
Where zonal OCR breaks#
Many layouts
An AP team with hundreds of suppliers, or a lender receiving statements from hundreds of banks, needs hundreds of templates. See bank statement extraction.Layout changes
A redesigned form or a new logo shifts fields out of their zones, often silently.Scan quality
Skew, scaling and cropping move text relative to the template.Variable-length content
Tables, line items and multi-line addresses don't fit fixed boxes.Maintenance
Every template must be built, tested and fixed when senders change formats.
Zonal OCR vs AI-based extraction#
| Aspect | Zonal OCR | AI-based extraction |
|---|---|---|
| How it finds a field | Fixed position on a template | Content, labels and layout context |
| New layouts | New template needed | Pre-trained models read unseen layouts; fine-tune for your own |
| Tables | Hard beyond fixed rows | Full tables, including multi-page |
| Setup | Quick for one layout | Quick for common documents with pre-trained models |
| Maintenance | Grows with every layout | Mostly handled by the model; corrections improve it |
| Best for | A few fixed layouts | Many senders, scans and changing formats |
AI-based platforms still let you point at a region when a document is unusual, but they don't depend on position. Docsumo, for example, has pre-trained models for invoices, bank statements, tax forms and ACORD forms, and can be trained on your own document types. See Docsumo Document AI.
- 99%field-level accuracy across 250+ document types
- 95%+of documents processed straight through, without manual review
How to choose#
What do your documents look like?
The bottom line#
Zonal OCR turns a fixed layout into structured data by reading only the boxes you define. It's simple and precise when documents never change, and costly to maintain when they do. If your documents come from many senders, AI-based extraction handles the variety without a template for each. For the API side, see our OCR API guide.
Book a demo to test it on your own documents, or start a free trial.
Frequently asked questions#
What is zonal OCR?
Zonal OCR is optical character recognition applied only to specific regions of a document, defined in a template. Each region is tied to a field, so the output is structured data, such as invoice number or date, rather than all the text on the page.
What is the difference between zonal OCR and full-page OCR?
Full-page OCR reads all the text on a page and returns it in reading order. Zonal OCR reads only the zones you define and labels each result with a field name.
What are the limitations of zonal OCR?
It depends on fixed positions. New layouts need new templates, small layout changes or skewed scans shift values out of their zones, and variable-length tables and multi-line fields are hard to capture.
What is the alternative to zonal OCR?
Template-free, AI-based extraction, often called intelligent document processing. It finds fields by what they look like and where they sit relative to labels, so it handles layouts it hasn't seen. See IDP vs OCR.
Sources
First published . Last updated .