The history of OCR technology: from reading machines to document AI
The key milestones in OCR history, with dates checked against primary sources. Each era says what it means for document automation today.
Key takeaways
- OCR began with telegraphy and reading aids around 1914, when Emanuel Goldberg built a machine that read characters and converted them into telegraph code.
- The first commercial reading machines came in the 1950s, from David Shepard's Intelligent Machines Research Corporation, founded in 1952.
- Banking adopted machine-readable characters early. The American Bankers Association chose the MICR E-13B font for checks in 1958.
- Omni-font OCR arrived in the 1970s with Ray Kurzweil, whose reading machine for blind people was unveiled in 1976.
- HP open sourced Tesseract in 2005, and version 4 added a neural network (LSTM) engine in 2018. Today OCR is one layer of document AI.
On this page
- OCR history at a glance
- Early reading machines (1914 to 1930s)
- The first commercial OCR (1950s)
- Banking and MICR (1950s to 1960s)
- Omni-font OCR (1970s)
- Desktop and open-source OCR (1980s to 2000s)
- Deep learning (2010s)
- From OCR to document AI (2020s)
- What a century of OCR means for your own test files
- Frequently asked questions
The history of OCR (optical character recognition) starts in 1914. That year Emanuel Goldberg built a machine that read printed characters and turned them into telegraph code. OCR technology then moved on in steps. Reading machines came in the 1950s and omni-font OCR in the 1970s. Desktop software followed in the 1980s, the open-source engine Tesseract in 2005 and deep learning in the 2010s. Today OCR is one layer of document AI, which reads business documents and checks the data.
The timeline below gives each date, checked against primary or well-documented sources. The sections after it say what changed in each era.
OCR history at a glance
- 1914, the first reading machinesEmanuel Goldberg builds a machine that reads characters and converts them to telegraph code. Edmund Fournier d'Albe builds the Optophone, which turns printed letters into tones.
- 1927 to 1931, the Statistical MachineGoldberg applies for a patent on an electronic microfilm search machine and demonstrates it in 1931.
- 1929 to 1935, Tauschek's reading machineGustav Tauschek files for a US patent on a "reading machine" in 1929; it's granted in 1935.
- 1952, the first OCR companyDavid Shepard, who built the GISMO reading machine with Harvey Cook Jr., founds Intelligent Machines Research Corporation.
- 1958, MICR for checksThe American Bankers Association adopts the magnetic-ink E-13B font for checks.
- 1974 to 1976, omni-font OCRRay Kurzweil founds Kurzweil Computer Products; his reading machine for blind people is unveiled in 1976.
- 1980s to 1990s, desktop OCROCR moves from dedicated hardware to software on PCs and flatbed scanners.
- 2005, Tesseract goes open sourceHP releases Tesseract, first developed at HP between 1985 and 1994.
- 2015, CRNNNeural networks read whole words and lines end to end.
- 2018, Tesseract 4The open-source engine adds an LSTM neural network engine.
- 2021 onward, transformers and document AITransformer OCR models such as TrOCR, layout-aware models and vision-language models.
Early reading machines (1914 to 1930s)
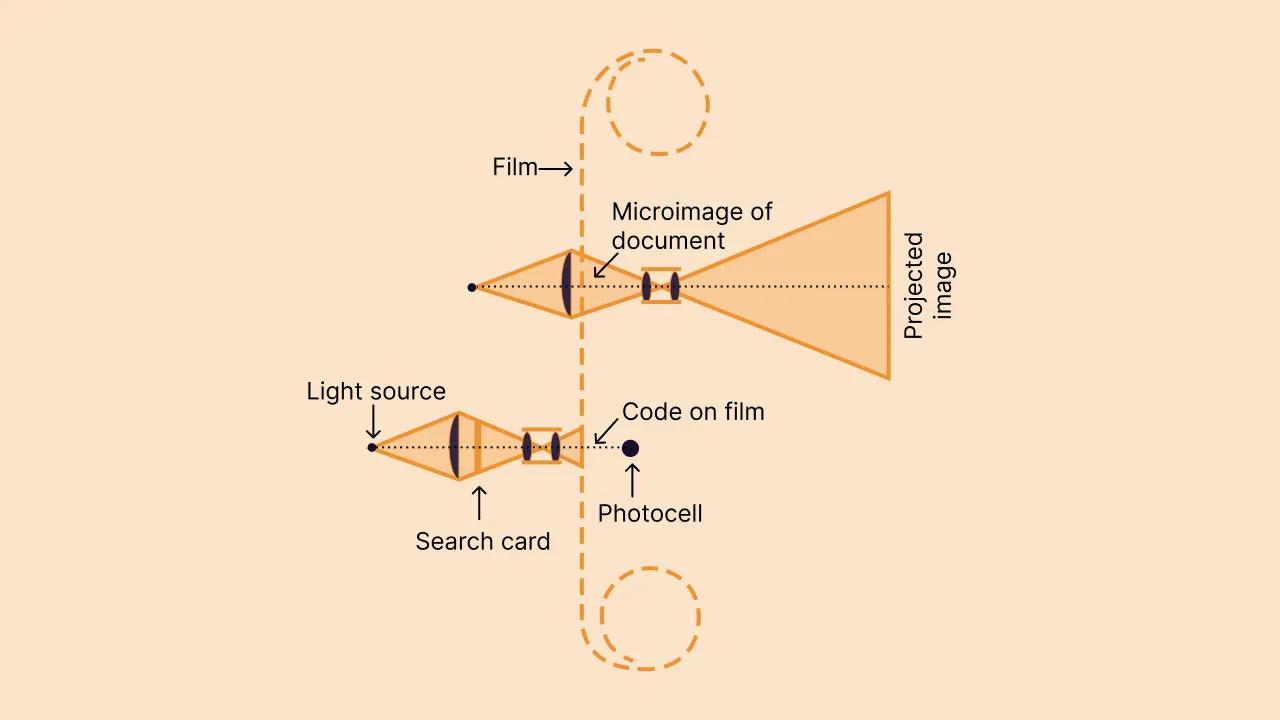
OCR began with telegraphy and with reading aids for blind people. Goldberg also built a Statistical Machine, patented after a 1927 application. It used a photocell (a light sensor) to search records stored on microfilm. When a code on the film matched the code on the search card, the light was blocked. The machine took that as a match. Historian Michael Buckland calls it the first working system to find documents using electronics.
In Vienna, Gustav Tauschek built a reading machine that compared each printed character with stored letter shapes (templates). It used light and a light sensor to do this.
The first commercial OCR (1950s)
IBM licensed the reading machine Shepard built, but never put it into production. The first major business use of OCR was reading credit cards. Shepard designed the Farrington B numeric font, which is still used on most credit cards.
Banking and MICR (1950s to 1960s)
Banks did not try to make machines read ordinary print. They designed special characters that machines could read easily. The first MICR checks were printed by the end of 1959. The standard was almost universal in the US by 1963, and every check still carries a MICR line. See OCR vs MICR.
Omni-font OCR (1970s)
Earlier systems could read only certain fonts. Kurzweil's system could read text in virtually any font. His reading machine was unveiled at a news conference with the National Federation of the Blind. A commercial version of the OCR software went on sale in 1978.
Desktop and open-source OCR (1980s to 2000s)
With PCs and flatbed scanners, OCR became software that turned scanned pages into editable, searchable text. After HP open sourced Tesseract in 2005, Google developed it from 2006 to 2017, and OCR spread to book digitization, cloud APIs and phone cameras. For a practical guide, see Tesseract OCR.
Deep learning (2010s)
Older systems told characters apart using rules that engineers wrote by hand. New models learned straight from images instead. CRNN (2015) was a neural network that read a whole line of text at once, not one character at a time. Tesseract 4 followed with its LSTM engine. Accuracy on messy scans, unusual fonts and handwriting improved sharply. For the algorithms, see text recognition algorithms.
From OCR to document AI (2020s)
Newer neural networks called transformer models, such as TrOCR (2021), read text more accurately. Layout-aware models learned where text sits on the page. Vision-language models can now look at a picture of a document and answer questions about it. The business question moved from "can the machine read this?" to "can it turn this document into data I can trust?"
- Scans
- Phone photos
- Image PDFs
- 01Read the text (OCR)
- 02Find the layout
- 03Extract named fields
- 04Check and review
Take one bank statement that an applicant photographed on a phone. The first step is the old OCR job. The software reads the text on the page, line by line, even though the photo is slightly tilted. The second step is newer. A layout-aware model finds where the transactions table starts and ends, and which column holds the dates and which the amounts. The third step picks out named fields, such as the account holder, the statement period and each transaction. Early machines stopped at the first step. Today the system also checks the extracted numbers against each other, and it sends any field it's unsure about to a person.
Our take. Test on your messiest files first. A tilted phone photo or a handwritten page shows more about a tool than any clean sample does. Early reading machines worked only on fonts built for them, and the gap between tidy input and real input has never fully closed.
That is intelligent document processing. Docsumo applies it to documents such as bank statements, ACORD forms and invoices. It reads 250+ document types at 99% field-level accuracy, and fields it's unsure about go to a person for review. See the platform or read what is OCR.
What a century of OCR means for your own test files
In a century, OCR went from photocells and template disks to neural networks that read almost any text. The step after reading is already here. Systems now check the data and act on it.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions
Who invented OCR?
There's no single inventor. Emanuel Goldberg built a character-reading machine in 1914. Gustav Tauschek patented a reading machine in the late 1920s. David Shepard built the GISMO reading machine and founded the first company to commercialize OCR in 1952.
When did OCR become widely available?
OCR moved from specialized hardware to desktop and commercial software during the 1980s and 1990s. Free, cloud and mobile services followed in the 2000s and 2010s.
What is the difference between OCR and MICR?
OCR reads characters optically from an image. MICR (magnetic ink character recognition) reads characters printed in magnetic ink, like the routing and account numbers on checks. See OCR vs MICR.
How did deep learning change OCR?
Neural networks replaced hand-built features. Models such as CRNN (2015) read whole lines of text at once, and Tesseract 4 (2018) adopted an LSTM engine. Accuracy on difficult text, including handwriting, improved sharply.
What comes after OCR?
Document AI, also called intelligent document processing. It adds layout understanding, language models and checks to OCR, so a document becomes usable data.
When was OCR invented?
The first machine that read printed characters was built in 1914 by Emanuel Goldberg, who converted them into telegraph code. OCR became a commercial product in the 1950s, when David Shepard founded Intelligent Machines Research Corporation in 1952.
Sources
- Buckland, M.: Emanuel Goldberg's Statistical Machine (UC Berkeley)
- Google Patents: US2026329A, Reading machine (Gustav Tauschek), granted Dec 31, 1935
- Wikipedia: David H. Shepard
- Wikipedia: Magnetic ink character recognition
- Wikipedia: Optical character recognition (history)
- GitHub: Tesseract OCR (history in README)
- GitHub: Tesseract 4.0.0 release (October 29, 2018)
- Shi, Bai, Yao: CRNN, arXiv:1507.05717
- Li et al.: TrOCR, arXiv:2109.10282
First published . Last updated .