OCR limitations: 6 disadvantages of OCR and how to fix each one
For teams whose OCR output still needs fixing by hand. Where optical character recognition breaks, what the errors look like on a degraded scan, and what closes each gap.
Key takeaways
- OCR limitations fall into six groups. Four are about reading: poor image quality, tables, handwriting, and unfamiliar fonts or languages. Two happen after the reading. OCR does not know what a value means, and it does not check whether a value is right.
- Start with the image. Tesseract's documentation says the software works best on images of at least 300 DPI. It also says a tilted page badly hurts how well Tesseract finds lines of text.
- OCR returns text, not data. It doesn't know which number is the invoice total, and it doesn't check that the total adds up.
- Intelligent document processing (IDP) starts from the OCR text. It rebuilds tables and names each field, such as invoice number, date and total. It also checks values and sends the fields it's unsure about to a person.
- OCR alone is enough for searchable text. Once values have to reach another system, you need the extraction and checks that come after it.
On this page
OCR limitations are the things optical character recognition can't do on its own. OCR misreads poor scans and loses the structure of tables. It struggles with handwriting and unfamiliar fonts or languages. It also returns plain text with no idea what a value means. Each limit has a fix. One fix is a better scan. Another is to add steps after OCR that find the fields, check them and send any uncertain fields to a person. Software that does those steps is called IDP, or intelligent document processing.
How the OCR process works, and where it stops
OCR turns a picture of text into characters. It cleans up the image, finds the lines and words, and matches each shape to a character. Modern engines read printed text in many languages and return each word's position on the page with a confidence score. They also make scanned PDFs searchable. On clean printed pages they're fast and accurate. What OCR hands back, though, is text and not data.
- Scanned PDF
- Phone photo
- Fax
- 01Clean up the image
- 02Find lines and words
- 03Recognize characters
What is OCR walks through each step of the process.
The 6 limitations of OCR technology
Picture one invoice that was faxed, stamped and scanned at low resolution. It is an ordinary document, but OCR makes six kinds of mistakes on it.
Image problems come first. Low resolution, a tilted page, faint ink, shadows and fax dots turn an 8 into a B. A stamp hides the date, and OCR reads one line of text as two. The fix is to scan at 300 DPI or more, and to straighten and clean the image before OCR.
Tables go wrong next. Columns move out of place and rows run together. A table that runs onto the next page comes back as separate lines of text with no table structure. Tesseract's own documentation says tables need custom layout analysis. Extraction that rebuilds tables, including ones that run across pages, closes this gap.
Handwriting comes next. Someone has written a 10 in the margin. OCR software trained on print misreads or skips handwritten entries, and some read only one language. Amazon Textract's handwriting support is English only. A model trained on handwriting helps, with unsure fields sent to a person.
Now suppose the scan is clear. Fonts and languages still cause trouble, because OCR software reads only the writing systems and fonts it was trained on. Stylized fonts, look-alike characters such as 0 and O, and mixed-language pages all produce misreads. Choose OCR software that covers your languages and test it on your real documents.
Two gaps remain, and both come after the reading. OCR returns "656.40" but not whether it is the total, the tax or one line's amount. Extraction that labels each value from its layout and context fixes that. OCR also scores how sure it is of each word, but it doesn't check whether a value makes sense. A wrong value that OCR is sure about then reaches your systems without anyone noticing. Checks such as line amounts that add up to the total, plus review of low-confidence fields, catch it.
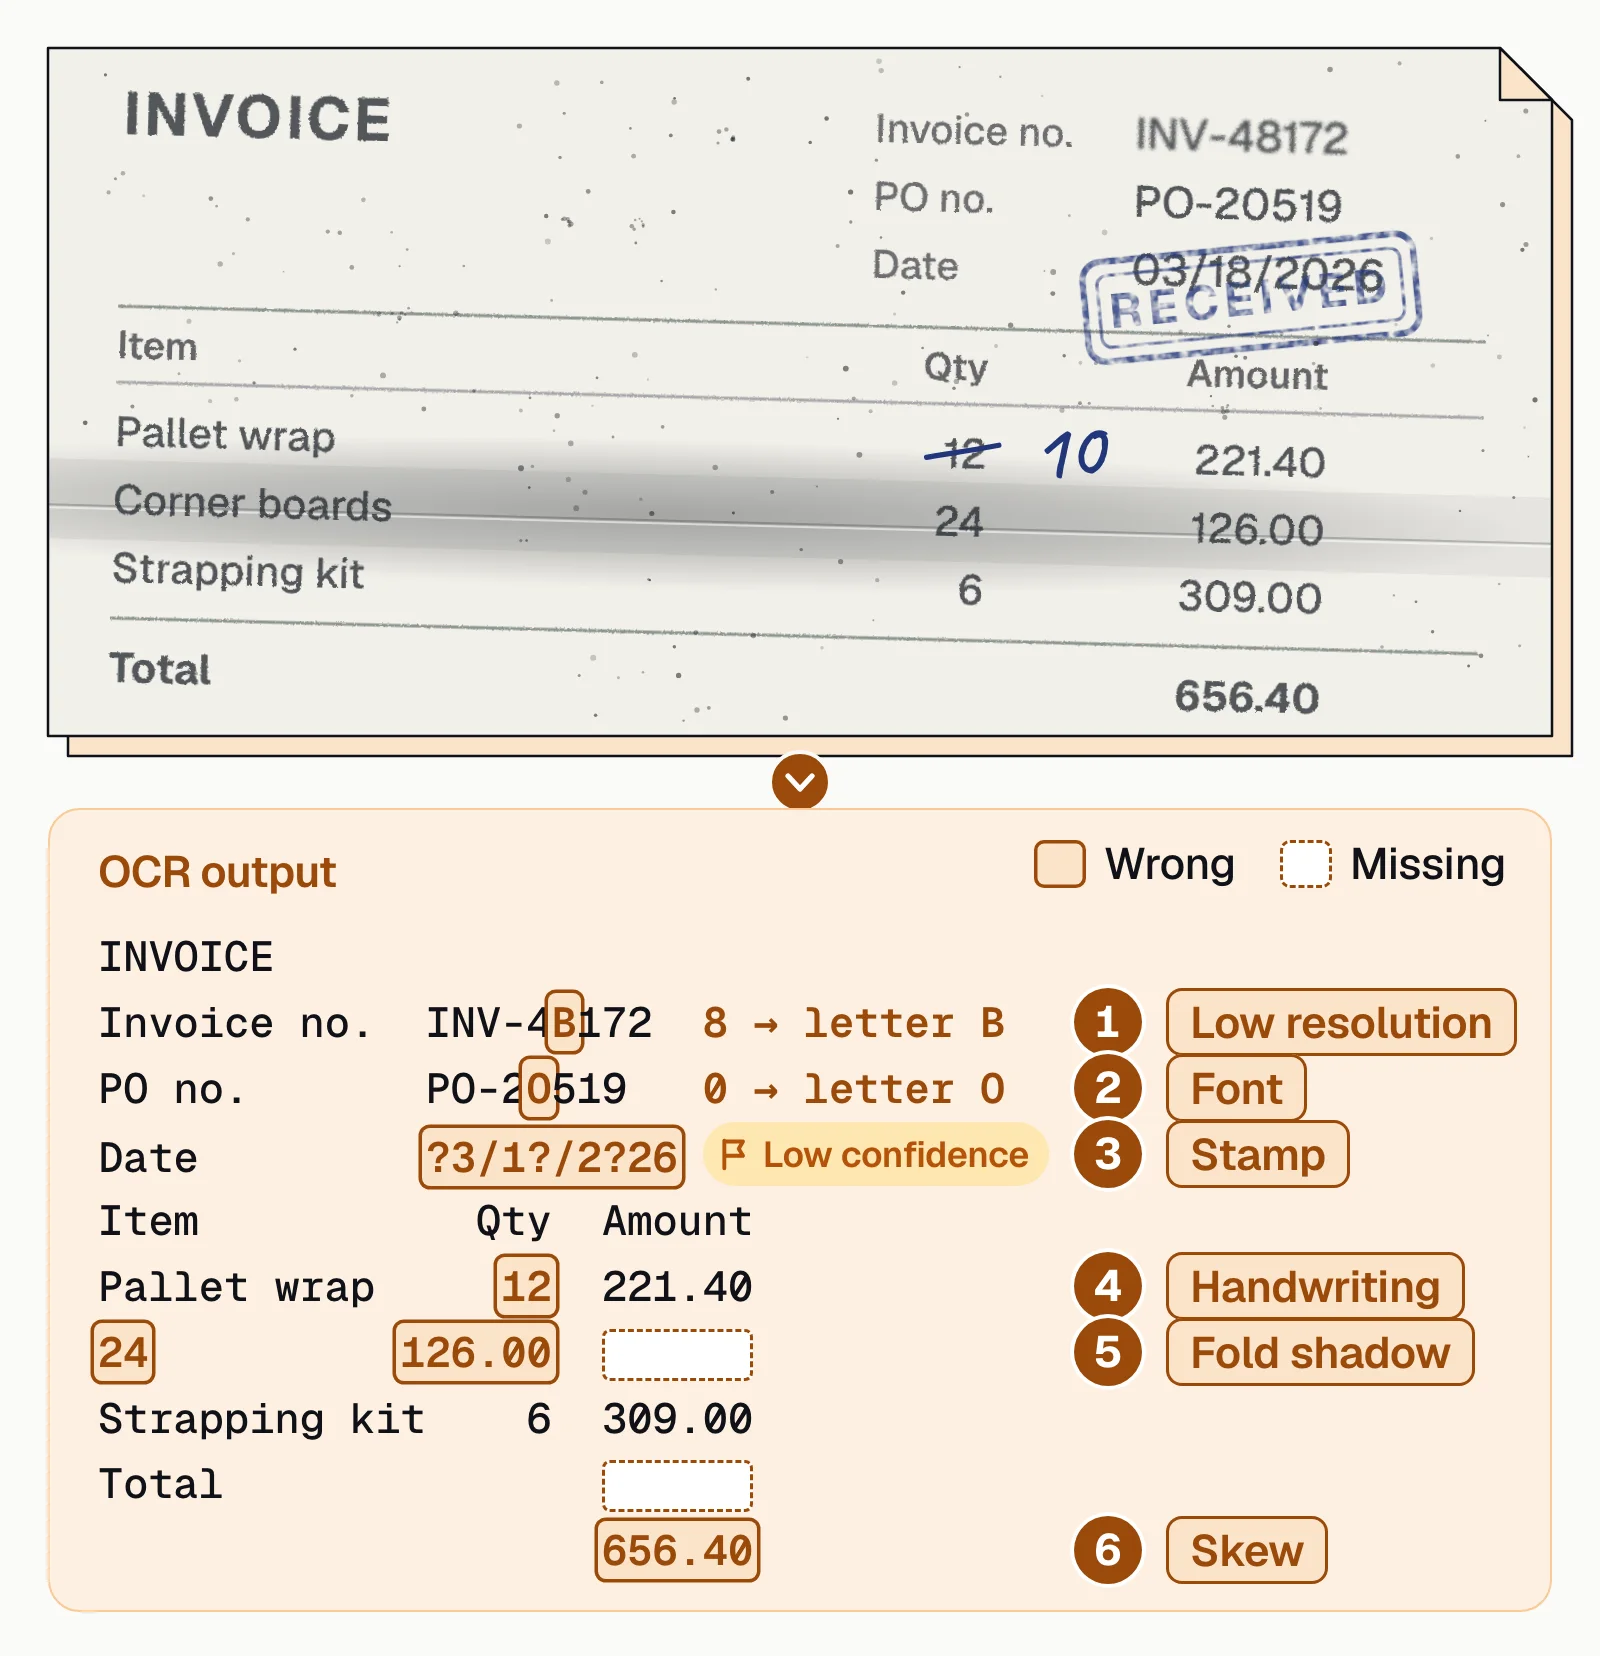
Real documents fail in the same places. In our OCR benchmark on 120 documents, the systems tested differed most on old scans, stamps, vertical text and small tables.
How to get better results from OCR
Before you change tools, fix the input. Tesseract's documentation notes that retraining the engine is unlikely to help, unless you use a very unusual font or a new language. It lists input fixes instead. Most apply to any OCR engine.
- Scan at 300 DPI or moreRescan or re-export low-resolution images rather than fixing misreads afterward.
- Straighten the pageDeskew so text lines run level; a tilted page breaks line finding.
- Clean the backgroundRemove speckle, shadows and dark scanner borders, which can be read as extra characters.
- Tell the engine what to expectSet the languages and the page layout, and limit fields such as amounts to digits.
- Handle tables separatelyUse layout analysis that finds the cells, or an extraction tool that rebuilds tables.
- Measure on your own documentsScore a sample field by field before and after each change.
Our take. Count what a person had to fix. Take a sample of your own documents and tally the fields someone corrected before and after each change. A single headline accuracy figure from any vendor, ours included, says much less than that count.
OCR alone vs OCR plus IDP
OCR alone is enough when you need searchable text: archiving, making scanned PDFs searchable or copying a paragraph. Once the values have to reach another system, what happens after OCR decides how much manual work is left.
OCR alone
- One block of text per page, not named fields
- Tables flattened into loose lines
- Misreads pass through unnoticed
- Someone keys and checks each value by hand
OCR plus IDP
- The invoice number, date and total, each in its own field
- Tables rebuilt, even across pages
- Unsure fields flagged for a person to check
- Checked values sent to your systems by API
IDP vs OCR covers the difference in more depth.
When a wrong value costs more than a retype
OCR reliably turns clean printed pages into text. Its limits show up on poor scans and tables, and on handwriting and unfamiliar fonts. They also show up after the text, where someone has to know what a value means and whether it's right. Fix the image first. Then, for documents where errors cost you, add extraction, checks and review. Docsumo does that for invoices, bank statements, ACORD forms and any other document type, with 99% field-level accuracy on 250+ document types. It reads printed and handwritten text, joins tables that run across pages and sends the fields it's unsure about to your reviewers.
Book a demo with a few of your hardest documents, or start a free trial.
Frequently asked questions
What are the limitations and disadvantages of OCR?
OCR misreads poor images and loses the structure of tables and multi-column pages. It struggles with handwriting and unfamiliar fonts or languages. It also returns plain text without knowing what a value means or whether it was read correctly. Intelligent document processing adds the steps that close those gaps.
Why isn't OCR 100% accurate?
OCR matches shapes to characters, so anything that distorts the shapes causes errors. Low resolution, skew, stamps, faint ink, decorative fonts and handwriting all do. Measure accuracy on your own documents, by field as well as by character; OCR accuracy explains how.
What can OCR do?
OCR turns printed text in scans, photos and image-only PDFs into machine-readable text. It makes scanned PDFs searchable and returns each word's position with a confidence score. Modern engines read many languages and some handwriting. It doesn't label fields or check values. Document processing adds that.
Can OCR read handwriting?
OCR trained on print reads handwriting poorly. Modern engines and document AI platforms read handwriting, but less reliably than print, and some only in English. Send low-confidence handwritten fields to a person; see handwriting recognition.
What is the difference between OCR and IDP?
OCR turns images of text into characters. Intelligent document processing uses OCR as its first step. It then classifies the document and extracts named fields. It checks them and sends unsure fields to a person before the data reaches your systems. See IDP vs OCR.
How do you add OCR to a document processing pipeline?
Call a cloud OCR API or run an open-source engine to get text and word positions. Then add the steps OCR doesn't do, which are table and field extraction, validation and a review screen. The best OCR APIs compares the options; a document processing platform includes those steps.
Sources
- Tesseract documentation: Improving the quality of the output
- AWS: Amazon Textract FAQs (language support)
First published . Last updated .