What is intelligent document processing (IDP)?
For operations, finance and IT teams that handle high volumes of documents: what IDP is, how each stage works, how it differs from OCR and RPA, and how to evaluate a platform.

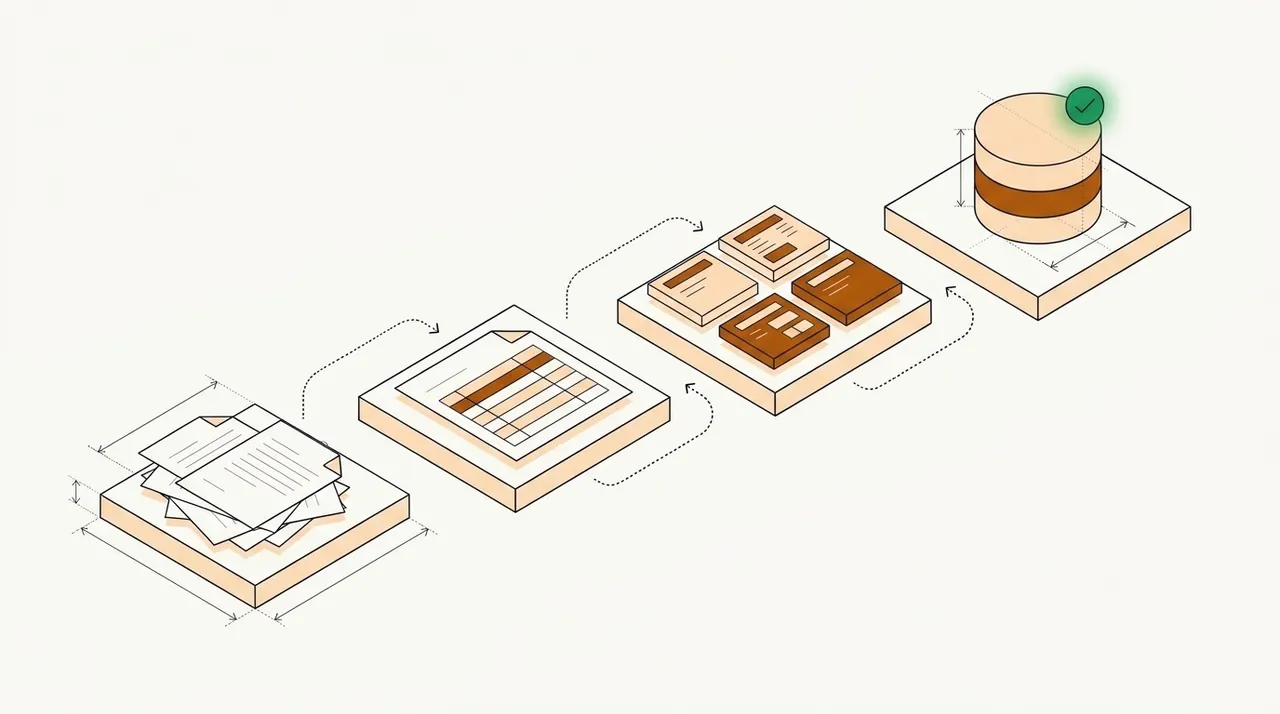
Key takeaways
- Intelligent document processing (IDP) is software that reads business documents, works out what each one is, pulls out the data you need and checks it before it goes into your systems.
- An IDP pipeline has six stages: ingest, classify, extract, validate, review and integrate. OCR is only the first step of extraction.
- Unlike template OCR, IDP handles structured, semi-structured and unstructured documents, including layouts it hasn't seen before.
- The goal is straight-through processing: documents that pass every check flow through untouched, and people only review the exceptions.
- Judge an IDP platform on field-level accuracy on your own documents, validation rules, the review experience, integrations and security certifications.
On this page
- What is intelligent document processing?
- How intelligent document processing works
- The technologies behind IDP
- IDP vs OCR, RPA and automated document processing
- Benefits of intelligent document processing
- Where IDP is used
- Common challenges, and how to handle them
- When IDP becomes essential
- How to choose an IDP platform
- The bottom line
- Frequently asked questions
Intelligent document processing (IDP) is software that reads business documents, such as invoices, bank statements, tax forms and insurance certificates, and turns them into structured, validated data. It combines OCR with machine learning and language models to classify each document, extract the fields you need, check them against rules and send them to your systems, so people only handle the exceptions.
This guide covers how IDP works stage by stage, the technologies behind it, how it compares with OCR, RPA and older automated document processing, where it's used, and what to look for when you choose a platform.
What is intelligent document processing?#
IDP is a category of software for turning documents into data. The "intelligent" part is that it doesn't depend on a fixed template: it understands what a document is and where the information sits, even when every vendor, bank or carrier lays out the page differently.
It works on three kinds of documents:
Structured
Fixed forms such as IRS tax forms or ACORD certificates, where each field has a set place.Semi-structured
The same information in different layouts, such as invoices, bank statements and pay stubs.Unstructured
Free text such as contracts, letters and emails, where the data has to be found by meaning.
Most business volume sits in the middle category, which is where template OCR breaks and IDP earns its keep. For more on the categories, see structured vs unstructured vs semi-structured data.
How intelligent document processing works#
A typical IDP pipeline has six stages. Each one removes a piece of manual work.
- Email inboxes
- Upload portals
- Scanners
- Cloud storage and API
- 01Ingest
- 02Classify
- 03Extract
- 04Validate
- 05Review exceptions
- IngestDocuments arrive from email inboxes, upload portals, scanners, cloud storage or an API. The platform normalizes PDFs, images and spreadsheets into one queue and cleans up images (deskew, denoise, rotate).
- ClassifyA model identifies each document type (invoice, bank statement, W-2) and splits multi-document packets into separate files. See document classification for how this works.
- ExtractOCR reads the text, then layout and language models locate the fields: the invoice total, the statement's closing balance, every transaction row. Good extraction keeps tables and relationships intact, not just loose text.
- ValidateExtracted values are checked with rules: totals add up, dates are valid, the name matches the application, the vendor exists in your master data. Cross-document checks compare values across files, such as income on a pay stub against deposits on a bank statement.
- ReviewAnything with low confidence or a failed rule goes to a person, who sees the flagged field next to its location on the page and corrects it. The rest passes through untouched. See human-in-the-loop review.
- IntegrateClean data goes to your ERP, loan origination system, CRM or database through an API, webhook or connector.
The technologies behind IDP#
| Technology | What it does in IDP |
|---|---|
| OCR and ICR | Converts printed text (OCR) and handwriting (ICR) in images into characters. Checkbox reading is sometimes called OMR. |
| Computer vision | Finds the layout: tables, key-value pairs, signatures, stamps and page regions. |
| Machine learning | Classifies documents and learns where fields sit across layouts from labeled examples and reviewer corrections. |
| Natural language processing and LLMs | Reads free text by meaning: party names in a contract, a description of operations, an email's intent. |
| Rules and validation | Applies business logic: math checks, formats, lookups against master data, cross-document comparisons. |
| Workflow and integration | Routes documents, assigns reviews, and pushes results to downstream systems. |
Large language models have changed IDP since 2023. They make it easier to read unfamiliar layouts without training data. But they can also produce confident, wrong answers, so production systems still pair them with field-level confidence scores, validation rules and human review. For more, see LLMs in document processing.
IDP vs OCR, RPA and automated document processing#
IDP is often confused with the tools it builds on. Here's how they differ:
| OCR | Automated document processing (ADP) | RPA | IDP | |
|---|---|---|---|---|
| What it does | Turns images of text into characters | Applies fixed templates and rules to capture known fields | Mimics clicks and keystrokes in applications | Classifies, extracts, validates and routes document data |
| Input it handles | Any image; output is unstructured text | Structured forms with a fixed layout | Structured data in applications | Structured, semi-structured and unstructured documents |
| New layouts | Reads the text but doesn't know what it means | Needs a new template | Not applicable | Handles most without a new template |
| Checks data | No | Basic rules | Only what the bot is scripted to do | Confidence scores, rules and cross-document checks |
| Improves over time | No | No | No | Yes, from reviewer corrections |
In practice, they work together. IDP uses OCR inside its extraction step, and an RPA bot or workflow engine can take IDP's output and key it into a legacy system that has no API. For a deeper comparison, read IDP vs OCR.
Benefits of intelligent document processing#
Less manual data entry
Teams stop retyping values from PDFs and spend their time on exceptions and decisions.Fewer errors
Validation rules catch the mistakes that slip through manual keying, such as transposed digits, wrong totals and mismatched names.Faster turnaround
Documents are processed in minutes rather than hours or days, which matters when a loan, claim or payment is waiting.Scale without hiring
Volume spikes at month end, renewal season or a marketing push are absorbed by the software, not overtime.An audit trail
Every value is linked to its source on the page and every correction is logged, which helps with audits and disputes.Fraud signals
Cross-document checks and tamper detection flag edited statements and inconsistent applications that a tired reviewer might miss.
For reference, these are Docsumo's published figures:
- 99%field-level accuracy across 250+ document types
- 95%+of documents processed straight through, without manual review
- <5 minper document, down from 2+ hours by hand
Where IDP is used#
| Team | Typical documents | What IDP does |
|---|---|---|
| Lending | Bank statements, pay stubs, tax returns, financial statements | Extracts and checks income, cash flow and balances for lending decisions |
| Accounts payable | Invoices, purchase orders, receipts | Captures header and line items and matches them against POs for AP automation |
| Insurance | ACORD forms, certificates of insurance, loss runs, claims | Reads submissions and COIs and checks them against requirements for insurance teams |
| Healthcare | Claims forms, eligibility documents, medical records | Extracts patient and claim data in a HIPAA-compliant environment |
| Commercial real estate | Rent rolls, operating statements, leases | Normalizes property financials for underwriting |
| Logistics | Bills of lading, delivery notes, customs forms | Captures shipment data for billing and tracking |
For more worked examples, see intelligent document processing examples.
Common challenges, and how to handle them#
Poor scans and photos
Image preprocessing helps, but set confidence thresholds so bad images go to review instead of passing silently.Document variety
Start with the highest-volume document types, measure accuracy on your own samples, and add types in phases.Format drift
A vendor or bank changes its layout and a model starts reading the wrong fields. Monitor accuracy by document source so a drop shows up in days, not weeks later in downstream errors.Mixed packets
One PDF can hold several documents with no clear page breaks. If classification and splitting miss a boundary, fields get pulled from the wrong document, so test with real combined uploads.Complex tables
Merged cells, spanning headers, multi-line items and tables that run across pages defeat simple extraction and come back as flat text. Check that row and column relationships survive.Overconfident models
A model can report high confidence on a wrong value. Validation rules are the backstop: a total that doesn't equal the sum of its lines should fail, whatever the confidence score says.Integration
Choose a platform with a documented API and webhooks, and plan where the data lands before you start.Security and compliance
Documents carry personal and financial data. Require certifications such as SOC 2 Type 2, and HIPAA or GDPR where they apply.Change management
Reviewers need a queue they trust. Show them where each value came from and let their corrections improve the model.
More detail in IDP challenges and how to solve them.
When IDP becomes essential#
IDP moves from nice to have to necessary when a few conditions line up. Check how many apply to your team:
- Volume outgrows the teamBacklogs build, SLAs slip and customers wait.
- Errors are expensiveA keying mistake in a loan file, claim or payment turns into rework, compliance findings or fraud losses.
- Speed wins businessFaster approvals or payments are a measurable advantage over competitors.
- Skilled people are keying dataUnderwriters, analysts and AP specialists spend hours typing instead of deciding.
Many companies are reaching that point. Precedence Research estimates the IDP market at $3.22 billion in 2025 and projects it to reach about $43.92 billion by 2034.
How to choose an IDP platform#
- Test on your own documentsAsk for field-level accuracy on a sample of your real files, including bad scans, handwritten sections, mixed packets and tables that span pages, not on a vendor demo set. Small gaps matter: at 10,000 documents a month, the difference between 95% and 99% accuracy is about 400 more errors to correct.
- Check the confidence thresholdsCan you set them by field or document type, and what happens to a value that falls below one?
- Check the validation layerCan you write rules, look up master data and compare values across documents?
- Look at the review screenReviewers should see low-confidence fields highlighted on the source page and fix them quickly.
- Confirm the integrationsAPI, webhooks and connectors to the systems you use today. See Docsumo's integrations.
- Check securitySOC 2 Type 2 at a minimum, with role-based access and audit logs. Docsumo's certifications are on the security page.
- Understand pricingMost platforms charge by page or document volume. Compare total cost at your real volume, and ask what a trial includes. Docsumo's plans are on the pricing page.
For a comparison of vendors, see the best intelligent document processing software. To test Docsumo against this list, start with its intelligent document processing platform.
The bottom line#
IDP turns documents into data you can trust: it classifies each file, extracts the fields, checks them and sends them on, and it leaves people only the documents that need judgment. The best way to judge any platform is to run your own documents through it and measure how many come out the other side with no human touch.
Book a demo with a few of your own documents, or start a free trial.
Frequently asked questions#
What is the difference between IDP and OCR?
OCR turns an image of text into machine-readable characters. IDP uses OCR as one step, then classifies the document, finds the specific fields you need, validates them and sends them to your systems. See IDP vs OCR for a side-by-side comparison.
Is IDP the same as RPA?
No. RPA automates clicks and keystrokes in applications using structured inputs. IDP turns unstructured documents into structured data. They are often used together, with IDP feeding clean data to an RPA bot or workflow.
What documents can IDP process?
Most business documents, including invoices, bank statements, pay stubs, tax forms, insurance forms, contracts and IDs. Docsumo reads 250+ document types with pre-trained models, and custom models can be trained for others.
Do IDP platforms use large language models?
Many now do. LLMs help with layout understanding, classification and reading unfamiliar formats. Production systems still pair them with validation rules and human review, because a confident wrong answer is costly in finance and insurance.
How long does it take to implement IDP?
It depends on document variety and integrations. Pre-trained models for common documents can run on day one; custom documents need labeled samples and testing. You can try Docsumo free for 14 days on up to 1,000 pages.