Text recognition algorithms: 10 methods behind modern OCR
For engineers and technical buyers: how modern OCR splits into text detection, recognition and decoding, the 10 algorithms that matter most, the open-source engines that use them, and what it all means for document extraction.
Key takeaways
- Modern OCR runs in three stages. Text detection finds where text is, text recognition reads each text region, and decoding and post-processing turn model outputs into words.
- Key detection algorithms are CTPN, EAST, CRAFT and DBNet; key recognition algorithms are CRNN with CTC, attention-based decoders and transformers such as TrOCR and PARSeq.
- CTC lets a model read a whole line without character-level alignment; word beam search constrains the output to a dictionary of valid words.
- Open-source engines package these ideas: Tesseract (LSTM since version 4), PaddleOCR, EasyOCR and docTR.
- For business documents, reading text is only half the job. Layout-aware models such as LayoutLMv3, and OCR-free models such as Donut, connect text to fields.
On this page
Text recognition algorithms are the methods OCR systems use to find text in an image and read it. Modern OCR splits the job into text detection (algorithms such as CTPN, EAST, CRAFT and DBNet find where the text is), text recognition (CRNN, attention decoders and transformers such as TrOCR read each region) and decoding (CTC and beam search turn model outputs into words). Open-source engines, among them Tesseract (LSTM since version 4), PaddleOCR, EasyOCR and docTR, package these algorithms for everyday use.
How modern text recognition works#
- Scans
- Phone photos
- Screenshots
- 01Preprocess the image
- 02Detect text regions
- 03Recognize each line
- 04Decode into words
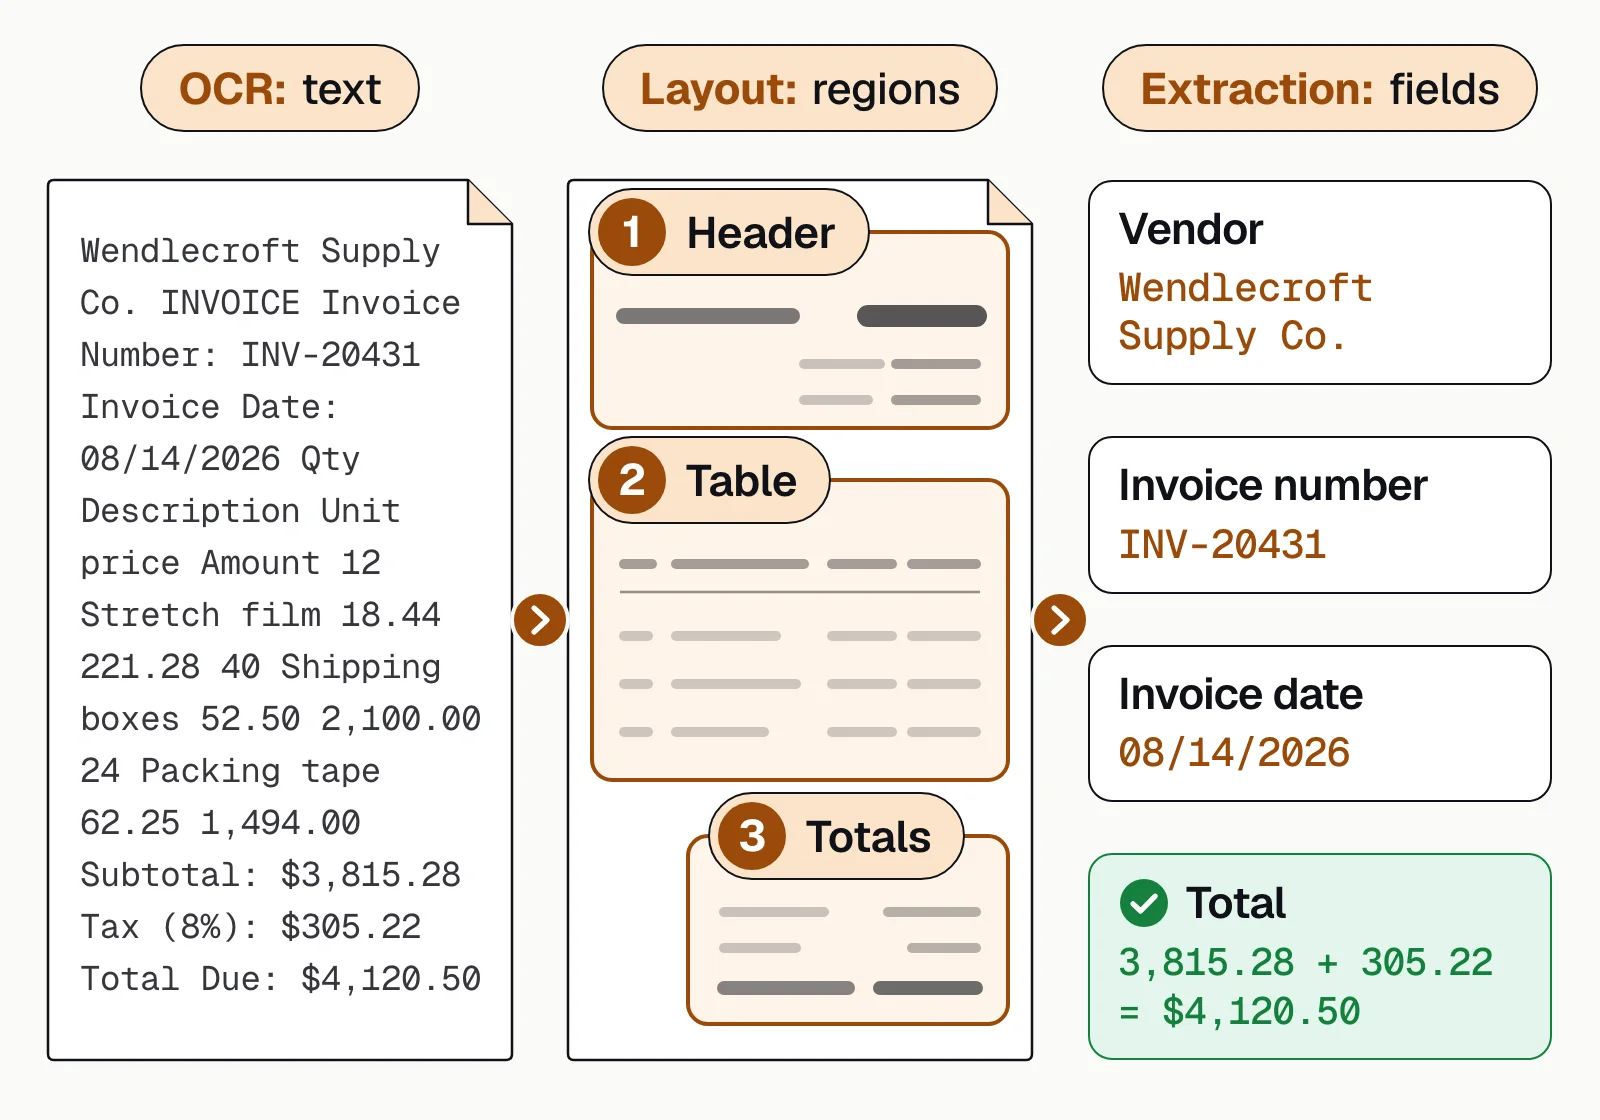
Take an invoice that arrives as a phone photo, tilted a few degrees and lit unevenly. Preprocessing straightens and cleans the image first, then a detector such as EAST or CRAFT draws a box around every line of text on the page, the vendor's address, each line item, the total, wherever the camera caught it.
Each box then goes to a recognizer. A CRNN reads the pixels inside a box as a sequence and, trained with CTC, outputs the characters without ever being told where one letter ends and the next begins; a transformer such as TrOCR can do the same job on a stamped or handwritten line. Decoding turns those per-step outputs into the most likely string for each box.
Older engines matched character shapes against templates, and trained networks like these have replaced that approach since the mid-2010s. Either way, what comes out is still loose text, not a field. Nothing yet has said which line is the total or checked it against the line items above it.
Four of the methods below are detectors, three are recognizers, CTC and word beam search are the training and decoding methods recognizers rely on, and the last reads documents rather than lines.
Text detection algorithms#
Detectors find where the text is and return boxes or polygons for the recognizer to read.
1. CTPN (2016)
The Connectionist Text Proposal Network links a row of thin, fixed-width text proposals with a recurrent network. Good on horizontal lines such as printed documents; weak on rotated or curved text.2. EAST (2017)
The Efficient and Accurate Scene Text detector predicts rotated boxes or quadrilaterals at every pixel in one fully convolutional pass. It's fast, which made it popular for real-time and mobile scanning.3. CRAFT (2019)
Character Region Awareness for Text detection finds each character and the links between characters, then groups them into words. Working at the character level helps with curved, irregular and widely spaced text.4. DBNet (2019)
Differentiable Binarization segments text regions and learns the binarization threshold during training, so it's both accurate and fast. Open-source engines such as docTR use it as a detector.
Text recognition algorithms#
Recognizers read the text inside each region. CRNN-style models are trained and decoded with CTC; attention and transformer models decode the text one step at a time.
5. CRNN (2015)
The Convolutional Recurrent Neural Network extracts visual features with convolutional layers, models the character sequence with LSTM layers and trains end to end with CTC. It reads a whole word or line at once and became the standard baseline.6. CTC
Connectionist Temporal Classification lets a network output a character sequence without knowing where each character sits in the image, by allowing "blank" outputs and merging repeats. Tesseract's LSTM engine, introduced in version 4, uses the same kind of sequence recognition.7. Attention-based encoder-decoders
Instead of CTC, an attention mechanism focuses on one part of the image for each character it generates. They handle irregular and curved text better, often after a rectification step that straightens it.8. TrOCR (2021) and PARSeq (2022)
Transformer recognizers. TrOCR pairs a pre-trained image transformer with a pre-trained text transformer and reads printed and handwritten text; PARSeq reads with or without language context and is a strong scene text recognizer.9. Word beam search
A CTC decoder that keeps words to a dictionary while still allowing numbers and punctuation between them. It improves word accuracy on handwriting when the vocabulary is known.
Understanding documents, not just text#
10. Layout-aware and OCR-free document models
Reading characters doesn't tell you which number is the invoice total. LayoutLMv3 (2022) combines text, position and image in one model, trained for tasks such as field extraction and document classification. Donut (2021) goes further. It's an OCR-free transformer that reads a document image and outputs structured data directly. Large vision-language models now do similar things at a higher cost per page.
Text recognition algorithms compared#
| Algorithm | Stage | Strength | Watch out for |
|---|---|---|---|
| CTPN | Detection | Horizontal text lines in documents | Curved or strongly rotated text |
| EAST | Detection | Speed; rotated boxes | Long or curved text |
| CRAFT | Detection | Curved and irregular text via character regions | Slower than lighter detectors |
| DBNet | Detection | Accurate and fast; arbitrary shapes | Needs good training data for your domain |
| CRNN + CTC | Recognition | Simple, fast, strong baseline for lines | Irregular or curved text |
| Attention decoders | Recognition | Irregular text | Can drift on long sequences |
| TrOCR, PARSeq | Recognition | High accuracy; TrOCR also reads handwriting | More compute |
| Word beam search | Decoding | Better word accuracy with a known vocabulary | Needs a dictionary |
| LayoutLMv3, Donut | Document understanding | Turns text and layout into fields | Needs labeled documents for your fields |
Open-source OCR engines#
| Engine | What it uses | License and latest release (checked Sept 2026) |
|---|---|---|
| Tesseract | LSTM line recognizer (since version 4), long-standing layout analysis | Apache 2.0; 5.5.3 (July 2026) |
| PaddleOCR | PP-OCRv6 detection and recognition models, plus PP-StructureV3 and the PaddleOCR-VL model for document parsing | Apache 2.0; 3.7.0 (June 2026) |
| EasyOCR | CRAFT detector and CRNN recognizer, 80+ languages | Apache 2.0; 1.7.2 (September 2024) |
| docTR | DBNet, LinkNet or FAST detectors; recognizers such as CRNN and PARSeq | Apache 2.0; 1.1.0 (August 2026) |
For a hands-on guide to the most common one, see Tesseract OCR.
How to choose#
What are you reading?
What we'd do. A paper's benchmark score describes the test set its authors picked, not the invoices, statements or leases your team reads. Before settling on Tesseract, PaddleOCR, EasyOCR, docTR or a paid API, run the candidates on a sample of your own documents and count what a person actually had to correct, rather than the number in the paper. That's the figure that predicts what happens once it's handling real volume.
From text recognition to document data#
For lending, insurance and finance teams, text alone isn't the target. What matters is the right value in the right field, the closing balance on a bank statement, the total on an invoice, the limits on an ACORD certificate. That takes recognition plus layout understanding, validation and review. Docsumo's document AI combines them to reach 99% field-level accuracy on 250+ document types. For how accuracy is measured, see OCR accuracy.
What the papers don't test#
Detectors such as EAST, CRAFT and DBNet find the text; recognizers such as CRNN with CTC and transformers read it; decoders clean up what's left. Every one of those methods was scored in a paper against images its own authors chose, not the invoices, statements or forms your team will run through it. Add layout-aware models, validation and human review on top of whichever pipeline you land on, so the output is data you can trust rather than just text.
Book a demo to see it on your own documents, or start a free trial.
Frequently asked questions#
What algorithm does OCR use?
Most modern OCR uses a deep learning pipeline, typically a convolutional or transformer-based detector to find text regions and a recognizer such as CRNN with CTC decoding, or a transformer, to read each line. Older OCR used template matching and hand-built features.
What is the difference between text detection and text recognition?
Detection finds where text is in an image and returns boxes or polygons. Recognition reads the characters inside each box. Some end-to-end models do both at once.
What is CTC in OCR?
Connectionist temporal classification is a training and decoding method that lets a model output a character sequence for a whole line without being told where each character sits in the image. It's used in CRNN and in Tesseract's LSTM engine.
Which open-source OCR engine should I use?
Tesseract is mature and runs anywhere, and works best on clean printed documents. PaddleOCR, EasyOCR and docTR use newer deep learning detectors and recognizers and often do better on photos and complex layouts. Test on your own images.
Do LLMs replace OCR algorithms?
Vision-language models can read text directly from images, and OCR-free document models like Donut skip a separate OCR step. For high-volume business documents, pairing dedicated OCR with layout models is still common because it's faster, cheaper and gives per-field confidence scores.
Sources
- Shi, Bai, Yao: An End-to-End Trainable Neural Network for Image-based Sequence Recognition (CRNN), arXiv:1507.05717
- Zhou et al.: EAST, An Efficient and Accurate Scene Text Detector, arXiv:1704.03155
- Tian et al.: Detecting Text in Natural Image with Connectionist Text Proposal Network (CTPN), arXiv:1609.03605
- Baek et al.: Character Region Awareness for Text Detection (CRAFT), arXiv:1904.01941
- Liao et al.: Real-time Scene Text Detection with Differentiable Binarization (DBNet), arXiv:1911.08947
- Li et al.: TrOCR, Transformer-based OCR with Pre-trained Models, arXiv:2109.10282
- Bautista, Atienza: Scene Text Recognition with Permuted Autoregressive Sequence Models (PARSeq), arXiv:2207.06966
- Kim et al.: OCR-free Document Understanding Transformer (Donut), arXiv:2111.15664
- Huang et al.: LayoutLMv3, Pre-training for Document AI with Unified Text and Image Masking, arXiv:2204.08387
- GitHub: CTC Word Beam Search
- GitHub: Tesseract OCR
- GitHub: PaddleOCR
- GitHub: EasyOCR
- GitHub: docTR
First published . Last updated .