OCR for claims processing: what to extract and how to automate it
For claims operations teams at carriers, TPAs and health plans: what OCR does in claims intake, which data to pull from each claim document, and why claims teams pair OCR with AI extraction and validation.
Key takeaways
- OCR claims processing converts scanned claim documents, PDFs and photos into machine-readable text so claim data doesn't have to be keyed by hand.
- Plain OCR only produces text. To get policy numbers, dates of loss, amounts, codes and VINs into the right fields, claims teams add AI extraction and validation on top.
- Each claim type has its own documents: CMS-1500 and UB-04 forms for health claims, estimates and police reports for auto, contractor invoices for property, first reports of injury for workers' compensation.
- The main obstacles are poor scans, handwriting, varied formats, sensitive data and integration with the claims system.
- A good setup sends only low-confidence fields and failed checks to an adjuster or processor, and everything else straight to the claims system.
On this page
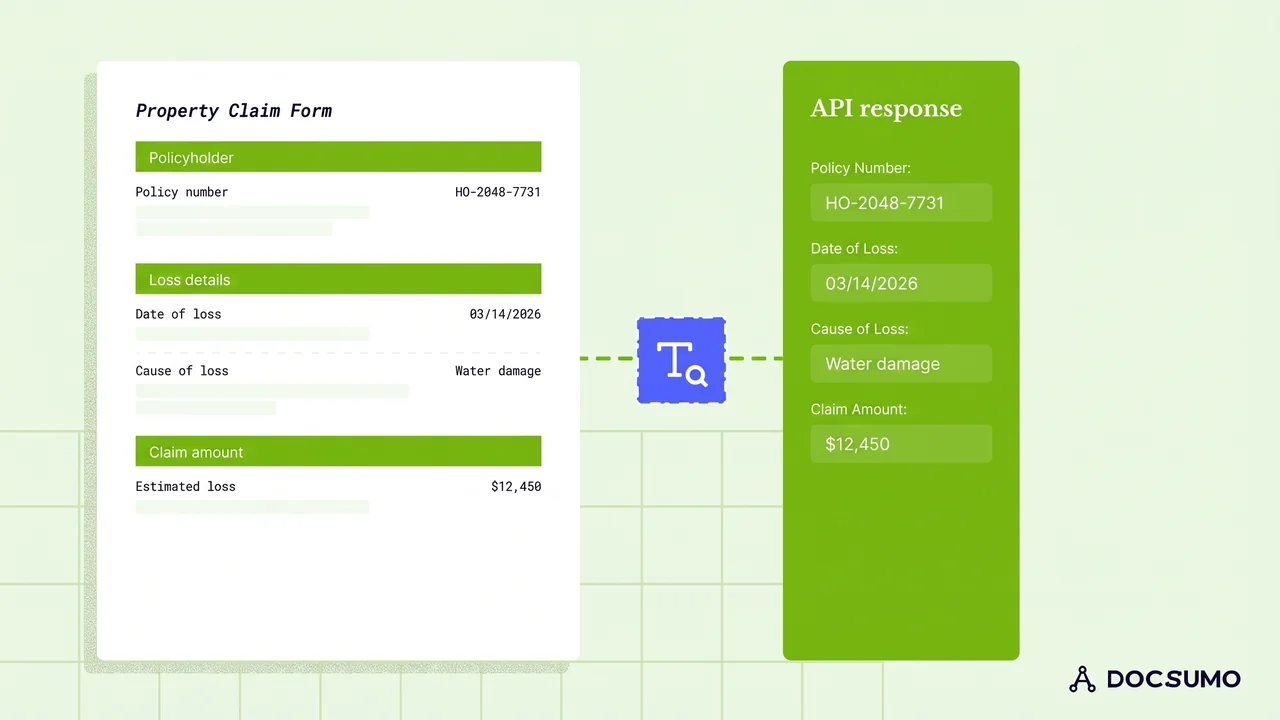
OCR claims processing is the use of optical character recognition to turn claim documents, such as claim forms, medical bills, repair estimates and police reports, into machine-readable text, so claim data doesn't have to be keyed by hand. OCR alone only produces text: claims teams add AI extraction to find the right fields, validation to check them, and a review step for anything uncertain.
This guide covers the documents and fields by claim type, the six steps from capture to claims system, and the problems to plan for.
What OCR does in claims processing#
Claim documents often arrive as scans, faxes, phone photos or flattened PDFs. OCR reads their characters, but it can't tell whether "03/14/2026" is the date of loss, the date of service or the date the form was signed. AI extraction uses layout and context to put each value in the right field.
Plain OCR
- Returns a block of text, not fields
- Finds fields only with a fixed template per layout
- Struggles with handwriting
- Turns itemized bills into loose lines
- Passes every value through unchecked
OCR plus AI extraction
- Maps each value to its field
- Works across layouts without templates
- Reads handwriting, with a confidence score per value
- Keeps itemized bills as tables, row by row
- Checks values and flags uncertain ones for review
On this property loss notice, the date of loss lands in its own field and is checked against the policy period:
| Field | Extracted value | Confidence |
|---|---|---|
| Policy number | QHM-5561204 | |
| Line of business | Homeowners (HO-3) | |
| Policy period | 2026-03-01 to 2027-03-01 |
| Field | Extracted value | Confidence |
|---|---|---|
| Insured name | Dana Whitlow | |
| Phone | (555) 010-2231 | |
| Contact note | Evenings (handwritten) |
| Field | Extracted value | Confidence |
|---|---|---|
| Date of loss | 2026-09-14 | |
| Cause of loss | Water: burst supply line | |
| Loss location | 212 Linden Ave, Fairhaven, LM | |
| Within policy period | Yes |
| Field | Extracted value | Confidence |
|---|---|---|
| Description | Burst supply line, kitchen and basement | |
| Estimated loss | 18,400.00 (handwritten) |
Documents and data by claim type#
Each claim type brings its own documents, and each document has a few fields that matter.
Health and medical
CMS-1500 and UB-04 reimbursement claims, itemized bills, EOBs and medical records. Fields: patient and insured IDs, provider NPI, dates of service, diagnosis and procedure codes, charges. See our health insurance claim form guide.Auto
Motor vehicle loss notice, police report, repair estimate and invoices. Fields: policy number, date and place of loss, vehicle year, make, model and VIN, parties, estimate totals.Property
Loss notice, contractor estimates and invoices, proof of ownership. Fields: policy number, property address, cause of loss, damage description, amounts.Liability
Loss notice, incident report, demand letter, medical bills. Fields: claimant, date and description of the incident, injuries, amount demanded.Workers' compensation
First report of injury, medical bills, wage statements. Fields: employee, employer, date and nature of the injury, treatment, wages.
How to extract data from claims documents, step by step#
- Portal uploads
- Fax and mail scans
- Mobile photos
- 01Capture
- 02Read with OCR
- 03Extract fields
- 04Validate
- CapturePull email, portal, fax, mail and mobile uploads into one queue.
- Clean up imagesStraighten, de-noise and sharpen scans and photos.
- Run OCRTurn each page into text with positions, handwriting included.
- ExtractClassify each document and pull its fields and tables: policy number, date of loss, codes, line items, totals.
- ValidateCheck that the policy was in force on the date of loss, totals add up, codes are valid and amounts agree across documents.
- DeliverSend the data to the claims system through an API and webhooks, and route exceptions to a processor or adjuster.
Benefits of OCR and AI in claims processing#
Claims reach adjusters without waiting for data entry, and catastrophe surges don't need temporary staff. Results for teams on Docsumo:
- <5 minper document, down from 2+ hours
- 99%field-level accuracy across 250+ document types
- $15saved per processed document
Challenges and how to handle them#
- Poor scans and handwritingClean up images first, and send low-confidence fields to review.
- Many formatsEvery body shop, contractor and provider has its own layout, so use extraction that needs no template per format.
- Sensitive dataRequire SOC 2 Type 2, HIPAA and GDPR coverage for medical and personal data.
- IntegrationPlan delivery into the claims system by API and webhooks early.
- Change managementWalk processors and adjusters through the review step before go-live.
Choosing software for claims document processing#
Look for pre-trained models for claim documents, handwriting support, table extraction, validation rules, a fast review screen and an API into your claims system. Docsumo reads claim forms, ACORD forms, estimates and medical bills for insurance and healthcare teams, and sends low-confidence fields to a reviewer. It isn't a claims system: it doesn't set reserves or pay claims. Compare claims automation tools.
The bottom line#
OCR is the first step in automating claims, not the whole answer. Pair it with AI extraction, validation and a review step, and claim documents become claim data that flows straight to adjusters and systems, with people handling only the exceptions.
Book a demo with a few of your own claim files, or start a free trial.
Frequently asked questions#
What is OCR in claims processing?
It's the use of optical character recognition to turn scanned or photographed claim documents into machine-readable text, so claim data can be captured and processed without manual typing.
Is OCR enough to automate claims intake?
Usually not. OCR gives you text but not which value is the date of loss or the billed amount. AI extraction, validation and a review step turn that text into claim data. See intelligent document processing for insurance.
Which claim forms can OCR and AI read?
Standard forms such as the CMS-1500, UB-04 and ACORD loss notices, plus unstructured documents such as repair estimates, invoices, police reports and medical records. See our guide to health insurance claim form extraction.
What is the difference between the CMS-1500 and the UB-04?
The CMS-1500 is the paper claim form for professional, non-institutional providers and suppliers, such as physicians. The UB-04, also called the CMS-1450, is the paper claim form for institutional providers such as hospitals. Both carry patient, insurance, provider, code and charge data, but in different layouts, so extraction has to handle each.
Can OCR read handwritten claim forms?
Modern OCR reads much handwriting, but accuracy drops on poor scans and messy writing, so keep a review step for low-confidence values. Docsumo reads handwritten text and sends the values it's unsure about to a reviewer.
Sources
First published . Last updated .